Best ML Platform Stack (2026)
An ML platform stack handles the full lifecycle from data preparation to model serving. Unlike the analytics-focused modern data stack, it adds experiment tracking, model training infrastructure, serving/inference endpoints, and often a lakehouse layer that connects governed data with ML/AI workloads. The key challenge is connecting data engineering (where the data lives) with ML engineering (where models are trained and deployed).
Who is this for?
- ML teams moving from notebooks to production pipelines
- Companies building their first ML infrastructure
- Data scientists who need reproducible training and deployment
- Teams evaluating SageMaker vs Vertex AI vs Databricks ML
How it works
Data is ingested and stored in a warehouse, lake, or lakehouse. ML engineers pull governed training data, run experiments tracked by an MLOps tool (MLflow, W&B), and train models using frameworks like PyTorch or TensorFlow. The MLOps platform handles the full lifecycle: experiment tracking, model training, registry, and deployment to serving endpoints. Optional orchestration coordinates data preparation, training, and batch inference jobs; an LLM API (OpenAI, Anthropic) can be added for generative AI features.
Scroll horizontally to inspect every architecture layer.
Evidence-backed reference architecture based on selected constraints, public adoption signals, product evidence, and available integration data. See how recommendations are scored.
Estimated cost: Pricing unavailable
Why this recommendation
- Optimized for a default ml platform architecture across the required stack layers.
- Prioritizes data storage and ML tooling that fit enterprise ML/AI platform workloads.
- Balances role fit, your stated requirements, and available integration evidence.
- Public activity is not part of Fit. It only separates candidates that fit equally well and are equally well evidenced.
Recommended tools
Data Ingestion
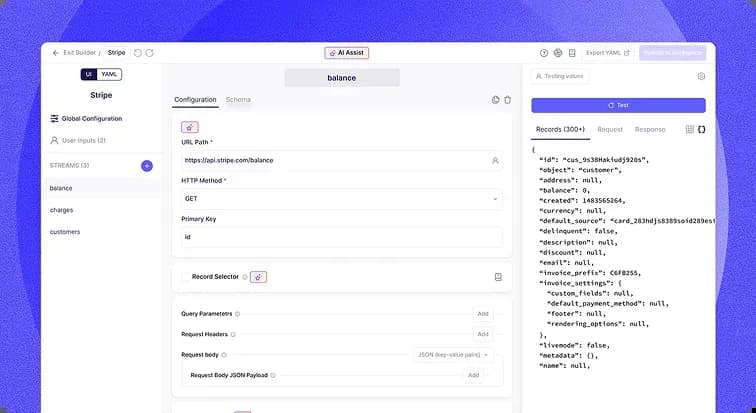
Open-source ELT platform with 600+ connectors and flexible self-hosted or cloud deployment
Airbyte and AWS Glue both meet every requirement you set for this layer. Nothing we can assess separates them, so Airbyte comes first by a fixed ordering rather than by any advantage over AWS Glue.
Runner-up: AWS Glue
Data Storage
Unified analytics and AI platform with lakehouse architecture combining data lake and warehouse
Databricks and Vertica both meet every requirement you set for this layer. Nothing we can assess separates them, so Databricks comes first by a fixed ordering rather than by any advantage over Vertica.
Runner-up: Vertica
Model Training
The next generation of Amazon SageMaker is the center for all your data, analytics, and AI
Amazon SageMaker and Azure Machine Learning both meet every requirement you set for this layer. Nothing we can assess separates them, so Amazon SageMaker comes first by a fixed ordering rather than by any advantage over Azure Machine Learning.
Runner-up: Azure Machine Learning
Model Serving
The next generation of Amazon SageMaker is the center for all your data, analytics, and AI
Amazon SageMaker and Azure Machine Learning both meet every requirement you set for this layer. Nothing we can assess separates them, so Amazon SageMaker comes first by a fixed ordering rather than by any advantage over Azure Machine Learning.
Runner-up: Azure Machine Learning
How recommendations change with your constraints
The same architecture adapts to your cloud, budget, and deployment preferences. Here's what our algorithm recommends for common scenarios:
Enterprise Lakehouse
Enterprise ML/AI platform stack where managed lakehouse, governance, and ML workload fit are weighted heavily.
Customize this scenario →AWS ML
AWS-first enterprise ML stack where AWS-native fit competes with lakehouse platform fit.
Customize this scenario →GCP-compatible + Python
Python-first ML stack that can run on Google Cloud.
Customize this scenario →Open Source ML
Fully open-source, self-hosted ML platform for teams that want full control.
Customize this scenario →Frequently asked questions
Do I need a separate ML platform or can I use my data warehouse?▾
You need both. The warehouse stores and prepares data; the ML platform handles training, experiment tracking, and model serving. They connect but serve different purposes.
MLflow vs Weights & Biases vs Neptune?▾
MLflow is open-source and integrates with everything. W&B has the best UI for experiment comparison. Neptune is lighter-weight. Our recommendation depends on your deployment preference and budget.
When is Databricks the right ML platform choice?▾
Databricks is strongest for managed enterprise ML/AI platforms where lakehouse storage, Spark, MLflow, notebooks, governance, and data engineering workflows need to live close together. AWS-native stacks may still prefer Redshift or SageMaker in specific slots when cloud-native fit matters most.
Build your ml platform
These recommendations use public adoption signals, product evidence, and verified integrations. Customize them for your specific requirements and review the methodology behind the available evidence.