Buying snapshot
Scroll sideways to see all columns. With a keyboard, focus this table and use the arrow keys.
| Decision point | What LocalAI states |
|---|---|
License | MIT. LocalAI describes itself as open source. |
Deployment | Self-hosted. Docker images for CPU only, NVIDIA CUDA 12 and 13, AMD ROCm, Intel oneAPI, Vulkan and NVIDIA Jetson, plus a macOS app. The website also lists Kubernetes. |
Hardware | x86_64 and ARM64 CPUs, with acceleration on CUDA, ROCm, SYCL, Metal and Vulkan. The website also lists Jetson and Raspberry Pi. LocalAI detects your GPU and downloads the matching backend. |
Where data runs | On your own hardware. The README lists it as "Privacy-first: your data never leaves your infrastructure". |
Users and access | API key auth, user quotas and role-based access. Version 4.1.0 added OIDC, and 4.9.0 made authentication deny-by-default. |
Help and business contact | Documentation and a Discord community. The website has a "Talk to us about your business" contact. |
Our take
Choose LocalAI if you want one self-hosted, MIT-licensed endpoint for chat, speech, vision and image work on hardware you already own, including servers with no GPU. If your plan depends on one engine-specific feature, test it on the exact backend you will run before you commit.
Evaluate LocalAI
Comparisons
Where it stands out
CPU path first. LocalAI says every feature ships a CPU path first, tested in CI, and that it is not a degraded fallback. A GPU makes it faster but is not required, so existing servers can run it.
Existing clients keep working. The API is OpenAI-compatible and also speaks the Anthropic, Ollama and ElevenLabs APIs, plus Realtime over WebRTC. LocalAI says most tools need only a URL change.
Engines are swappable per model. LocalAI supports 60+ backends, including llama.cpp, vLLM, SGLang, whisper.cpp, diffusers and MLX. Each backend is pulled only when a model needs it, and switching a model's engine is one line in its config.
Grows from one box to a cluster. Distributed mode scales horizontally with PostgreSQL and NATS. LocalAI states it handles VRAM-aware placement, prefix-cache affinity, autoscaling and failover, and that in-flight work reschedules when a node is lost.
Large model gallery with its own quantisations. The gallery holds 1,255 models, including 201 APEX builds. In LocalAI's own test on an NVIDIA DGX Spark, APEX Mini cut Qwen3.5-35B-A3B from 64.6 GB (F16) to 12.2 GB and ran at 74.4 tokens a second, against 30.4 for F16.
Agent built into the binary.
local-ai chatstarts an agent that runs shell commands behind an approval gate you control, delegates to sub-agents and loads MCP servers, plugins and skills.
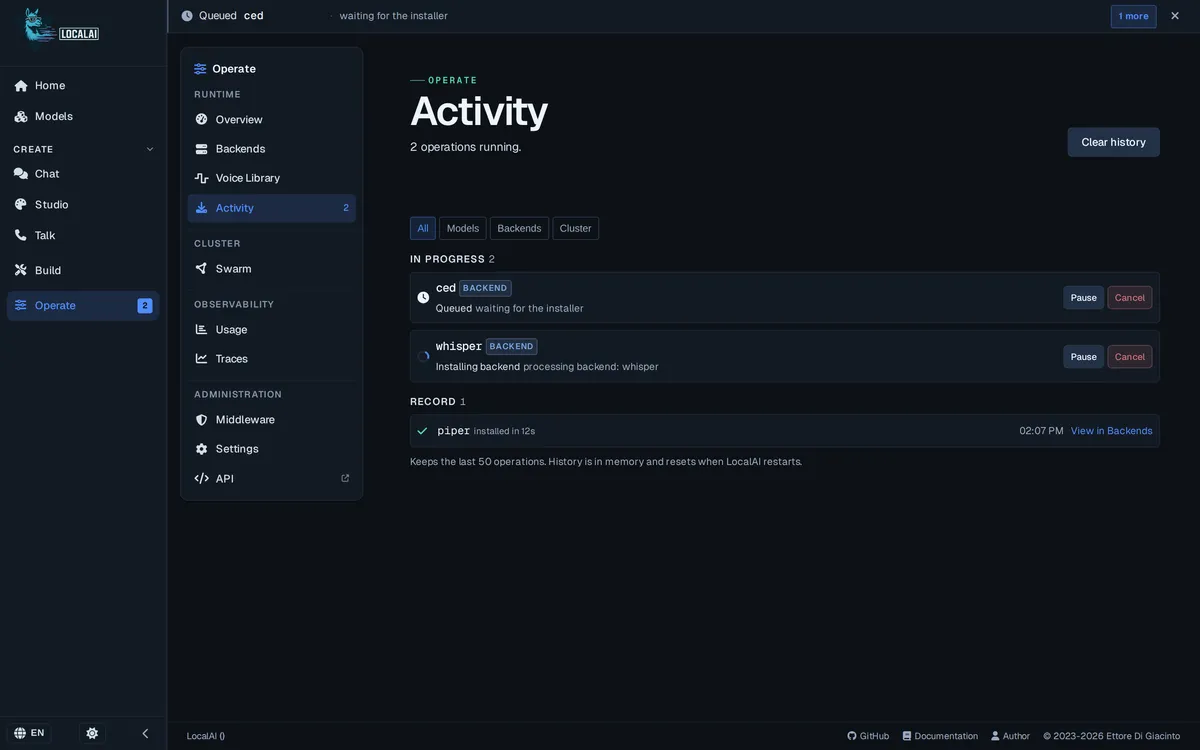
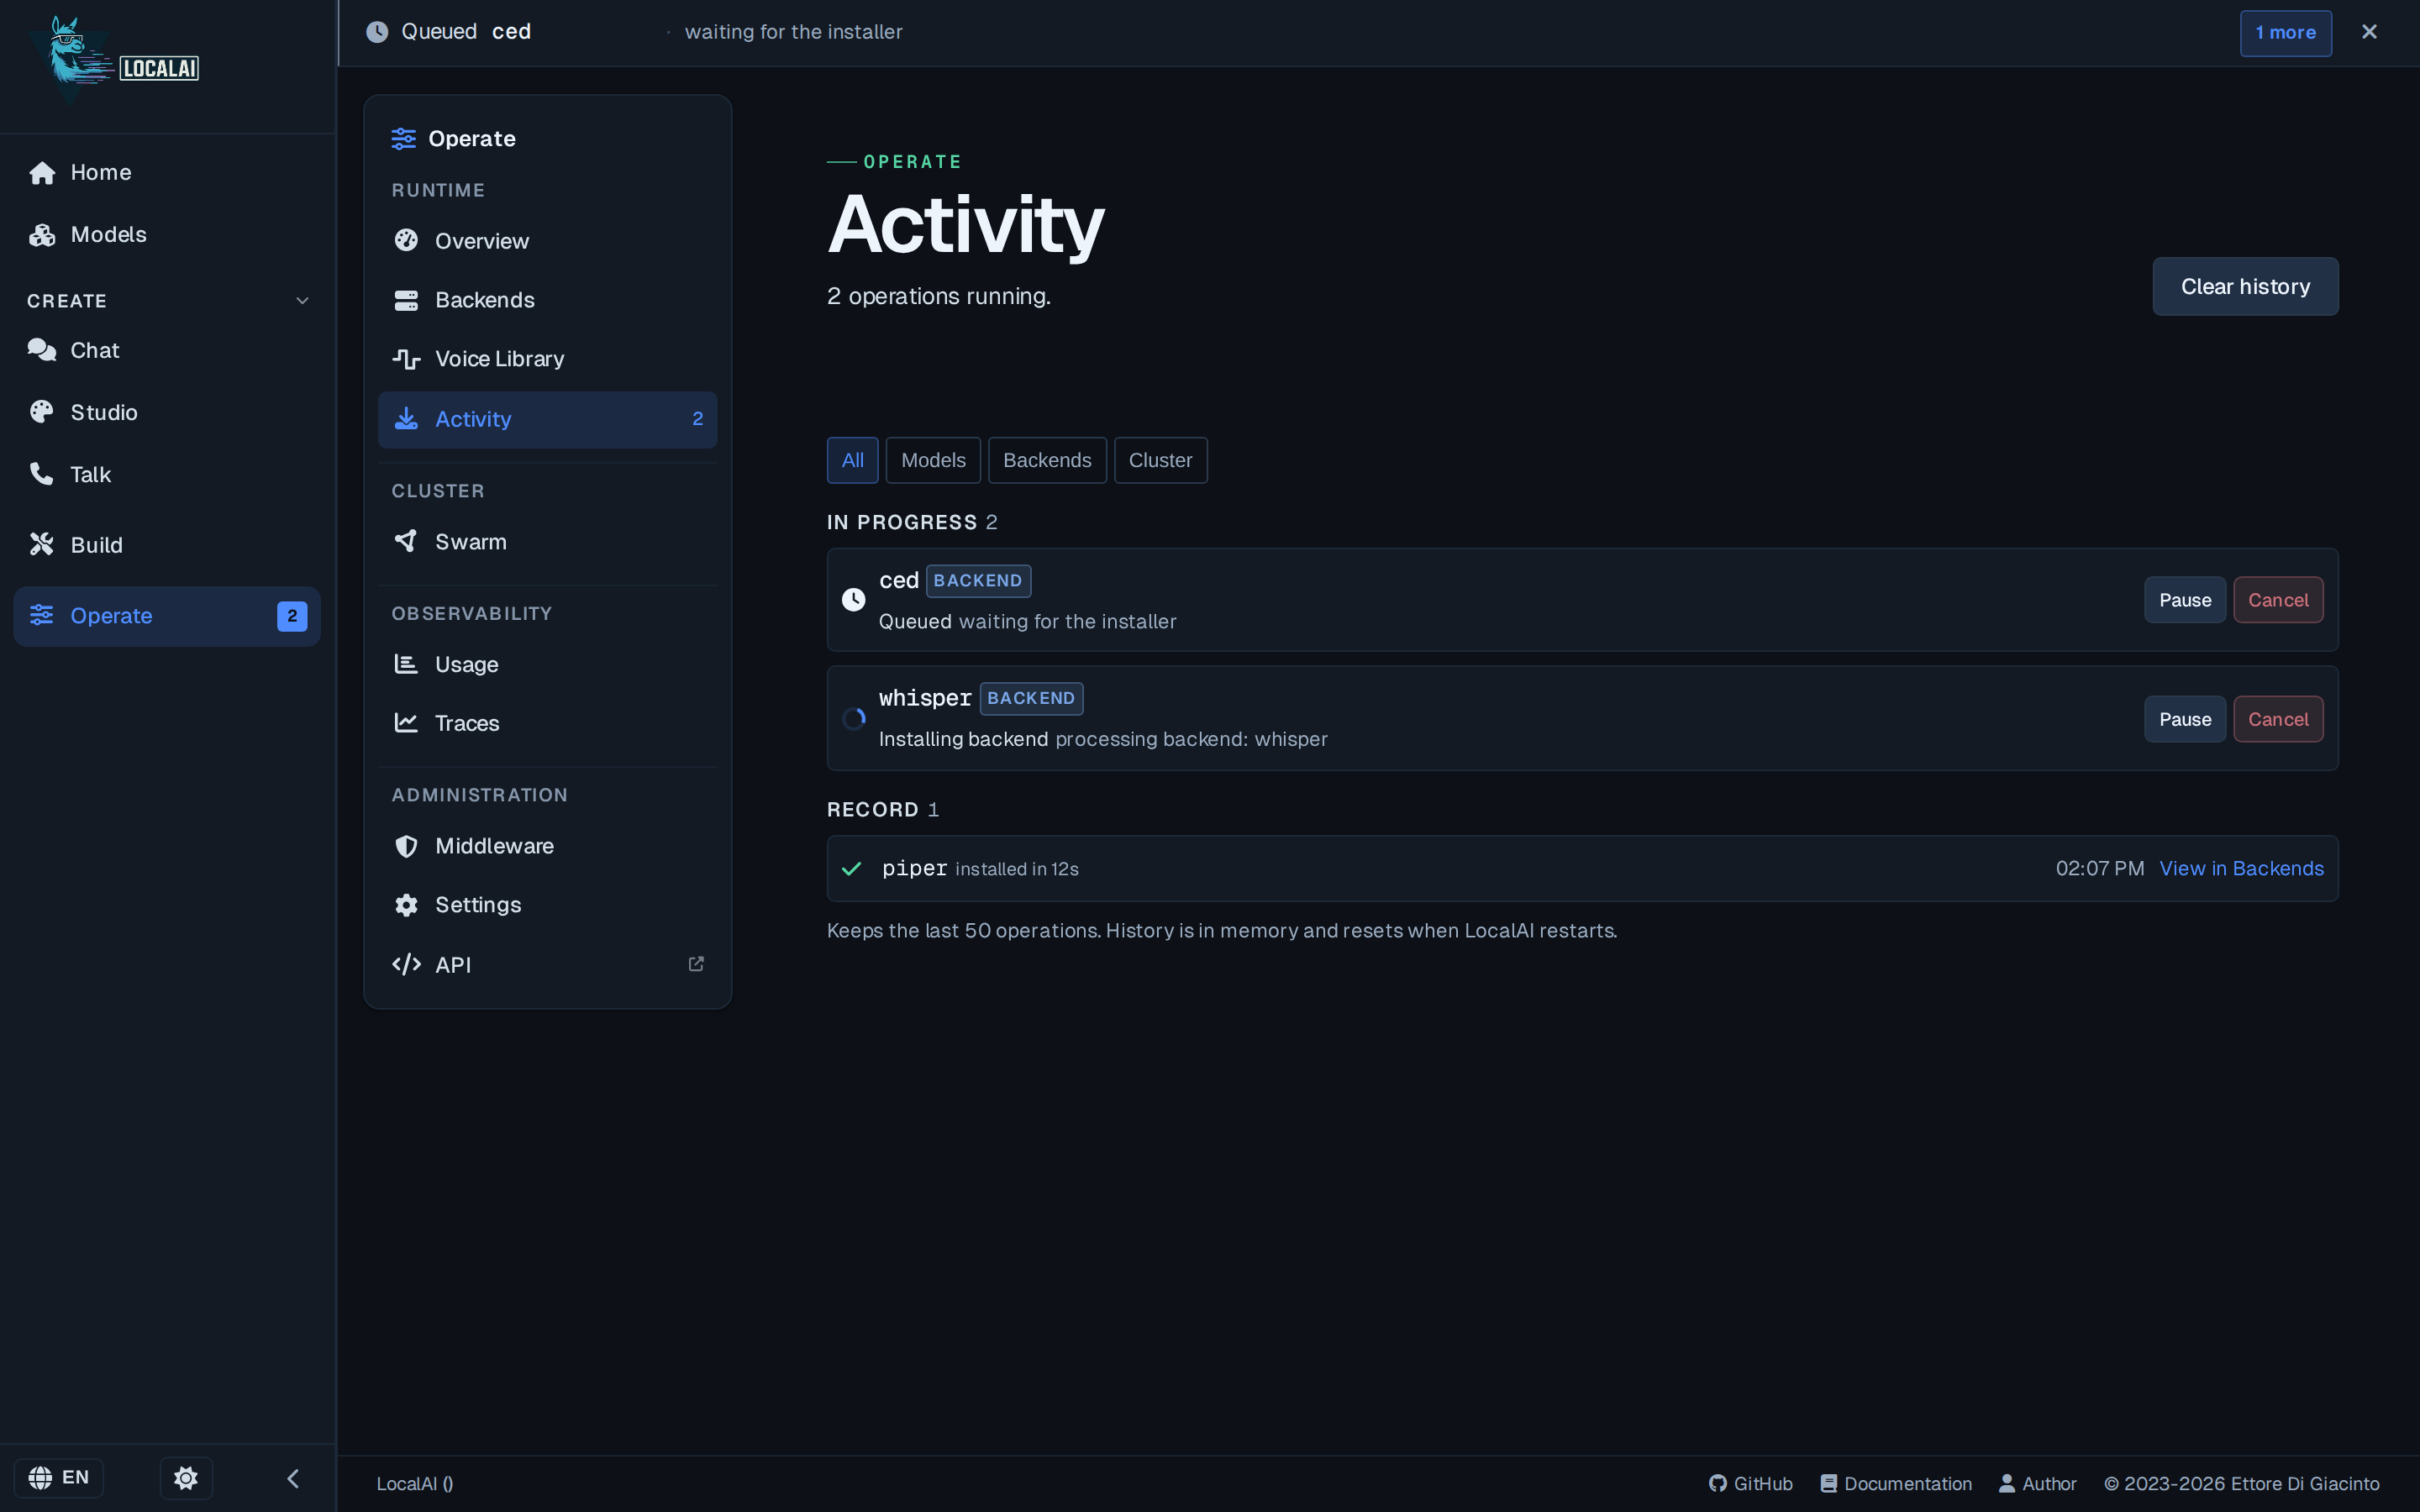
Product screenshot
Trade-offs to weigh
Features depend on the backend. Some APIs work with one engine only. For example, the slot save and restore API is for llama-cpp only, and other backends return 501. Breadth means you check each feature against the backend that serves your model.
Some CPU backends need newer CPUs. The ik-llama-cpp backend, aimed at large models on CPU, requires AVX2 support, and its IQK kernels do not work on older CPUs.
Some new engines are early. vllm.cpp, LocalAI's own C++ port of vLLM with paged KV cache and continuous batching, arrived in 4.8.0 as alpha development builds.
Frequent releases mean upgrade work. Releases 4.5.0 through 4.11.0 all shipped between June and October 2026. Some change behaviour: 4.9.0 made authentication deny-by-default, so plan to re-test access after upgrades.
The macOS app is not signed by Apple. After installing the DMG you must clear the quarantine flag with a
sudo xattrcommand.
Pricing and plan conditions
LocalAI is MIT-licensed software that you install and run yourself, so the bill comes from the machines it runs on and the people who operate it. The project pitches starting on a laptop you already own and scaling to a room full of GPUs when you need more capacity. The main cost drivers are the hardware your models need, the number of nodes in distributed mode, and time spent choosing and tuning backends.
Public signals
About these signals
Verified factual signals from public sources. They indicate observable activity or interest, not total adoption, product quality, or cost.
1.5k GitHub commits 90d50.0k GitHub stars
See all signals from 4 sources
Alternatives to LocalAI
The reviewed substitutes for LocalAI among the model runtimes, and what would make each one the better answer.
Direct alternatives
Reviewed substitutes: products bought for the same job, where a team picks one.
- Ollama
- Choose Ollama when the workload is chat or coding on one machine and you would rather decide nothing; choose LocalAI when the endpoint has to cover more than text.Applies to: Choosing between two products of the same kind for one job.
Other approaches
A different approach to the same problem. Each substitutes only for the workload named beside it.
- vLLM
- vLLM is used rather than LocalAI for high-throughput text serving workloads on a discrete GPU, where the extra runtime layer adds nothing. **vLLM** is the choice when text throughput is the binding constraint.
- Fireworks AI
- Fireworks AI is used rather than LocalAI for pay-per-token serverless inference workloads where the specific model version matters more than keeping the runtime in-house. **Fireworks AI** covers similar ground with pay-per-token serverless inference over open models and trial credits for new accounts.
- Groq
- Groq is preferred over LocalAI for latency-sensitive interactive workloads where time-to-first-token is the felt product quality. **Groq** runs open models on custom LPU silicon built for low-latency inference, billed per token. It is the one to evaluate when time-to-first-token is the felt product quality rather than throughput or cost.
- Replicate
- Replicate is used rather than LocalAI for image, video, and audio generation workloads billed by compute second rather than by token. **Replicate** bills per second of compute rather than per token, with published hardware rates from CPU through GPU tiers.
- Together AI
- Together AI is chosen instead of LocalAI for open-weight inference workloads that outgrow local hardware and can accept prompts leaving the network. **Together AI** removes the operational cost entirely, serving open weights over a managed API from $0.04 per million input tokens for small models to $3.00 input and $15.00 output per million for the largest, with no capacity to plan and no monthly floor.
Related technologies
Normally used together rather than chosen between, so these are not alternatives.
- Hugging Face
- Hugging Face is the model hub these runtimes pull from, not a competing way to run a model locally. The runtime fetches weights from the Hub and serves them on the user's own machine, which is a supply relationship rather than a choice: a team running one is using the other. Recorded as complementary so it stays off the alternatives grid instead of presenting a registry as a substitute for a local server. The extractor proposed this one as a conditional alternative and derive withheld it, noting a replacement sentence could not be attributed to both products. That withholding was right: none exists, because the two are not on the same side of any decision.Applies to: Running an open-weight model on your own hardware behind an OpenAI-compatible API: LocalAI is the server, Hugging Face is the source of the weights.