Buying snapshot
Scroll sideways to see all columns. With a keyboard, focus this table and use the arrow keys.
| Decision point | What Matillion states |
|---|---|
Cloud data platforms | Maia Foundation provides connectors, orchestration and governance across Snowflake, Databricks, BigQuery and Redshift. |
Deployment | Hosted SaaS, a hybrid deployment, or inside Snowflake itself. Hybrid cloud deployment on your own hosted agent infrastructure is a Scale edition feature. |
Connectors | 150+ pre-built connectors for structured, semi-structured and unstructured data. You can build a custom connector to a REST API without code, or ask Matillion to build a Flex Connector, which it says it delivers in days. |
Security controls | Single sign-on on every edition, with custom SSO only on Scale, plus multi-factor authentication and role-based access control. |
Reliability | Matillion states 99.9% uptime through a fault-tolerant agent model and paired cloud data centers. |
Our take
Choose Matillion when your pipelines land in Snowflake, Databricks, BigQuery or Redshift and you want one tool where people can build them on a visual canvas, in SQL or Python, or hand the work to AI agents. If you already run Matillion ETL or Data Productivity Cloud, both remain fully supported, and you can add Maia when you are ready: Matillion says it is an addition, not a replacement.
Evaluate Matillion
Popular comparisons
See all 6 Matillion comparisons
Where it stands out
Processing stays in your data platform. Matillion uses a native pushdown architecture on Snowflake, Databricks and Amazon Redshift, and says data never leaves your cloud platform. This matters where policy limits copies of data outside the platform.
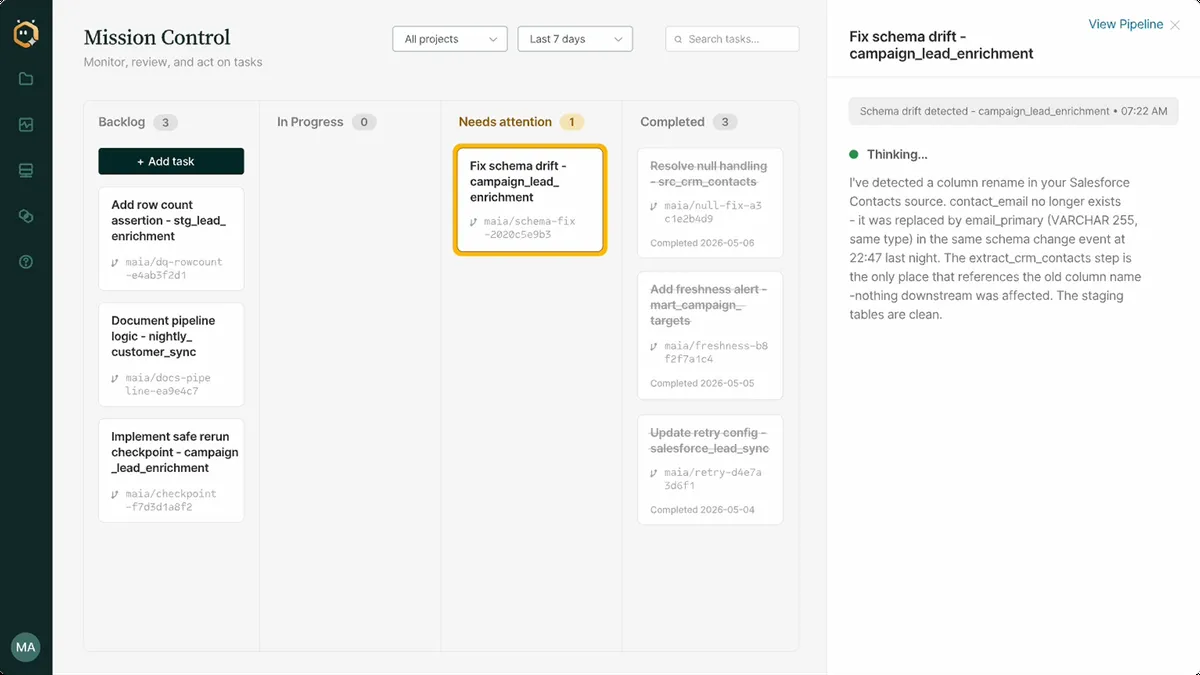
AI agents with a review step. Maia Team agents plan, build, test, deploy and fix pipelines, and you review every plan before it runs. Mission Control runs tasks in the background and shows everything in flight. Matillion also says its Migration Agent, announced in April 2026, converts legacy ETL pipelines from 14 platforms to cloud data warehouses.
Language models inside pipelines. Prompt components bring large language models into a pipeline to transform and enrich data. Other components load vector stores for retrieval-augmented generation without code, and reverse ETL sends results back into source systems.
Product screenshot
Trade-offs to weigh
"Unlimited users" does not mean unlimited builders. The product page promotes unlimited users and no per-user limits, but only admin users are unlimited. Developer users, the people who build pipelines, come in a fixed number per edition, so count your builders before you choose an edition.
One edition per account. An edition applies to everything in its subscription, and a Data Productivity Cloud account can have only one active subscription. If only some teams need Scale features, you either put the whole account on Scale or run separate accounts with separate subscriptions.
Run time drives credit use. Task hours add up the execution time of every task in a pipeline run, so frequent schedules and long-running pipelines consume more credits.
Pricing and plan conditions
Matillion bills in credits, its smallest unit of charge. Credits are consumed by task hours, which are charged only while a pipeline runs, and by developer users beyond those your edition includes. Validation and sampling are not billed. Matillion sells fixed annual packages with included credits, shows credit use in a consumption tracking dashboard, and asks you to contact it to buy more credits.
Scroll sideways to see all columns. With a keyboard, focus this table and use the arrow keys.
| Edition | Positioned for | Included users | What the edition includes |
|---|---|---|---|
Developer | Individuals; light workloads and early exploration | 1 developer user, unlimited admin users | Unlimited projects, pre-built connectors, low-code canvas with SQL and Python components, and a built-in Git repository. Community support, built-in SSO only, 90-day log retention. |
Teams | Scaling businesses | 5 developer users, unlimited admin users | Everything in Developer, plus an audit log, standard customer support and a Service Level Agreement included with an annual subscription. Built-in SSO only, 90-day log retention. |
Scale | Large organizations | 5 developer users, unlimited admin users | Everything in Teams, plus custom SSO, hybrid cloud deployment, data lineage, streaming change data capture, bring-your-own Git and 180-day log retention (365 days available). Premium Support is available as an add-on. |
Where to buy: contract directly with Matillion, or pay through your AWS, Azure or Snowflake account and subscribe through your cloud marketplace.
Trials: a free trial is offered, and Maia can be tried for free in Data Productivity Cloud on a time-bound, fair-use basis.
Public signals
About these signals
Verified factual signals from public sources. They indicate observable activity or interest, not total adoption, product quality, or cost.
Top 77% Google Trends search interest0 Hacker News matching stories, 90d
See all signals from 3 sources
Alternatives to Matillion
The reviewed substitutes for Matillion among the ETL platforms, and what would make each one the better answer.
Direct alternatives
Reviewed substitutes: products bought for the same job, where a team picks one.
- Talend
- Matillion and Talend both extract, transform and load data into cloud warehouses with visual pipeline design, scheduling and governance. Matillion is cloud-native and built around warehouses such as Snowflake, BigQuery and Redshift, while Talend, now part of Qlik, covers a wider suite of data integration, data quality and application integration.Applies to: Choosing the enterprise integration suite that will run data pipelines.
Other approaches
A different approach to the same problem. Each substitutes only for the workload named beside it.
- Fivetran
- Fivetran and Matillion both load data from SaaS applications and databases into cloud warehouses such as Snowflake, BigQuery and Redshift. Fivetran runs managed connectors that land the data and keep schemas in step; Matillion adds a visual job designer that builds the transformations and runs them in the warehouse.Applies to: Loading SaaS and database data into a cloud warehouse. Fivetran stands in where the team wants hands-off connectors and models the data afterwards in SQL or dbt; Matillion stands in where loading and transformation are built in one visual tool.
- Prefect
- Prefect and Matillion both cover running data pipelines on a schedule and in dependency order. Matillion bundles that with its visual ETL and ELT designer for cloud warehouses, while Prefect is a Python-native orchestrator where pipelines are written as code and run from a managed cloud control plane.Applies to: Whether pipelines are scheduled inside the ETL suite or coordinated by a separate orchestrator.
- Apache Airflow
- Apache Airflow and Matillion can each run data pipelines on a schedule and in the right order. Matillion builds that orchestration into its visual ETL designer next to the transformations, while Airflow keeps orchestration separate as open-source Python code that can trigger jobs in any tool.Applies to: Whether pipelines are scheduled inside the ETL suite or coordinated by a separate orchestrator.
- Dagster
- Dagster and Matillion can both decide when data pipelines run and which steps wait on which. Matillion handles this inside its commercial visual ETL platform, while Dagster is an open-source orchestrator that models pipelines as data assets, with lineage and testing built in.Applies to: Whether pipelines are scheduled inside the ETL suite or coordinated by a separate orchestrator.
- dbt (data build tool)
- dbt (data build tool) and Matillion both transform data inside cloud warehouses such as Snowflake, BigQuery and Redshift. dbt is an open-source SQL framework for analytics engineers who work in code with version control and tests, while Matillion is a commercial platform with a visual job designer that also loads the data, which suits teams that prefer building pipelines on a canvas.Applies to: Deciding how the stack is shaped, where both products can be part of the answer.
Head to head
See detailed alternatives analysis
If you are evaluating Matillion alternatives, you are likely looking for a data integration and transformation platform that better fits your team's technical depth, deployment preferences, or budget constraints. Matillion is a cloud-native ETL/ELT platform with a visual job designer built for warehouses like Snowflake, BigQuery, Redshift, and Azure Synapse. It combines low-code pipeline building with SQL and Python support, making it accessible to both technical and non-technical users. However, teams frequently explore other options when they encounter pricing complexity with credit-based consumption models, need open-source flexibility, want fully managed ingestion without transformation overhead, or require deeper orchestration capabilities beyond what Matillion provides natively.
Top Alternatives Overview
Airbyte is an open-source ELT platform offering a large connector library for replicating data from hundreds of sources into warehouses, lakes, and databases. Its open-source core and connector development kit make it attractive for engineering teams that want full control over their data pipelines. Airbyte can be self-hosted at no cost or used as a managed cloud service, The platform focuses on the extract-and-load layer and integrates with dbt for transformations, creating a modular pipeline architecture.
Fivetran is a fully managed ELT platform that emphasizes automated data ingestion from SaaS applications, databases, and event streams. With its catalog of fully managed connectors, Fivetran handles schema evolution, incremental updates, and connector maintenance automatically. Fivetran is designed for teams that want reliable data movement without building or maintaining pipelines, differentiating itself from Matillion's more hands-on visual designer approach. It also offers hybrid deployment for teams with strict security requirements.
dbt Cloud takes a different angle as a transformation-focused platform. Rather than handling data extraction and loading, dbt Cloud enables analytics engineers to build, test, and document data models using SQL. It is commonly paired with an ingestion tool like Fivetran or Airbyte to form a complete data pipeline. Teams that find Matillion's combined ETL/ELT approach overly broad may prefer dbt Cloud's focused transformation workflow with built-in version control, CI/CD, and a semantic layer for consistent metric definitions.
AWS Glue is a serverless data integration service within the AWS ecosystem. It provides ETL capabilities for discovering, preparing, and loading data for analytics, along with a Data Catalog for metadata management. AWS Glue is particularly well-suited for organizations already committed to the AWS stack, offering native integration with S3, Redshift, and other AWS services. Its pay-per-use pricing based on compute consumption contrasts with Matillion's credit-based model.
Confluent is a data streaming platform built on the heritage of Apache Kafka, designed for real-time data integration and event-driven architectures. While Matillion operates primarily in batch mode, Confluent enables continuous data streaming, making it relevant for teams that need real-time data movement alongside or instead of batch-based ETL processes. Confluent offers both managed cloud and self-managed deployment options.
Stitch is a cloud-first ETL/ELT tool focused on simplicity, moving data from SaaS applications and databases into cloud warehouses with minimal configuration. Stitch targets smaller teams or those with straightforward data integration needs who find Matillion's feature set more complex than necessary, offering a low barrier to entry for basic data replication workflows.
Architecture and Approach Comparison
, a cloud-native platform that generates native SQL executed directly within your cloud data warehouse (Snowflake, Databricks, Amazon Redshift) through pushdown processing. This means data transformations leverage your warehouse's compute power rather than running on Matillion's servers, and data never leaves your cloud platform during processing. The platform supports low-code visual pipeline design alongside SQL, Python, and dbt, accommodating mixed-skill teams. Matillion also provides a hybrid deployment option and a stateless microservices architecture called PipelineOS that enables containerized agents to run massively in parallel for high-throughput workloads.
Airbyte's architecture is container-based, running each data sync as isolated Docker containers for source and destination connectors. This microservices approach enables strong process isolation and horizontal scaling -- failures in one sync do not cascade across other pipelines. The open-source edition gives teams full access to the codebase and the ability to deploy on their own infrastructure using Docker or Kubernetes. Airbyte focuses exclusively on data movement (extract and load) and relies on external tools like dbt for the transformation layer, creating a more modular but multi-tool pipeline architecture.
Fivetran takes a fully managed approach where the platform handles all infrastructure, connector maintenance, and pipeline orchestration. Teams interact through a configuration-driven interface rather than building pipeline logic manually. Fivetran deduplicates data changes on its own servers before writing to the destination, reducing warehouse compute consumption. The platform includes built-in transformation orchestration through dbt integration, reverse ETL capabilities, and a hybrid deployment option that lets data movement run within your own environment when required.
dbt Cloud operates purely at the transformation layer, running SQL-based models directly within your cloud data warehouse. Its architecture is built around the concept of analytics as code: version-controlled transformations, CI/CD pipelines, automated testing, data lineage, and a semantic layer for consistent metric definitions. The Fusion engine provides fast model execution and cost-efficient compute. Since dbt Cloud requires a separate ingestion tool upstream, it creates a clear separation of concerns that many teams pair with Fivetran or Airbyte for a complete ELT stack.
AWS Glue uses a serverless architecture with automatic scaling and no infrastructure management required. It provides both visual ETL job authoring and code-based Spark or Python jobs, along with the AWS Glue Data Catalog for centralized metadata management. The tight integration with AWS services makes it a natural choice for AWS-centric environments, though this same integration creates platform dependency that limits portability.
Confluent's architecture is fundamentally different from batch-oriented tools. Built on Apache Kafka as a distributed streaming platform, Confluent processes data continuously rather than on scheduled intervals. Its connector ecosystem enables real-time data movement across systems, making it suited for operational analytics, event-driven microservices, and use cases where batch latency is unacceptable. The platform offers managed cloud deployment as well as self-managed options for teams that need infrastructure control.
Pricing Comparison
Matillion publishes three Data Productivity Cloud editions: Developer, Teams, and Scale. Pricing is consumption-based: customers use credits for Matillion resources, with pipeline task hours charged when pipelines run. Credits may also be consumed for additional Developer users beyond those included with an edition.
Developer is intended for individuals and includes one developer user, unlimited admin users, unlimited projects, pre-built connectors, a low-code canvas, SQL/Python components, and a built-in Git repository. Teams includes five developer users, unlimited admin users, audit logging, standard support, and an SLA with an annual subscription. Scale also includes five developer users and adds custom SSO, hybrid cloud deployment, streaming change data capture, data lineage, extended log retention, bring-your-own Git integration, and an option for Premium Support.
The pricing page does not list public currency amounts, included credit quantities, credit rates, or a public price for any edition. It describes fixed annual packages with included credits and says subscriptions can be contracted directly with Matillion or paid through AWS, Azure, or Snowflake accounts. Before buying, confirm the edition, annual subscription terms, included credits, task-hour consumption rates, additional Developer-user charges, and any required add-ons.
When to Consider Switching
Consider moving from Matillion to Airbyte if your team has strong engineering capabilities and wants open-source flexibility. Organizations that need to self-host their data integration infrastructure, want to avoid vendor lock-in, or need to control costs at scale by managing their own deployment will find Airbyte's open-source model compelling. Teams that primarily need data movement without built-in transformation may prefer Airbyte's focused approach paired with dbt over Matillion's broader but tightly coupled platform.
Switch to Fivetran if your primary need is automated, hands-off data ingestion from a large catalog of sources. Fivetran is particularly strong when your team wants to minimize engineering effort on pipeline maintenance and connector updates. Organizations that value managed infrastructure and prefer to pair ingestion with a separate transformation tool like dbt may find Fivetran's fully managed approach less burdensome than Matillion's visual designer workflow, especially for teams where reliability and compliance certifications are priorities.
Consider dbt Cloud if your team's primary challenge is data transformation and modeling rather than data ingestion. Teams with SQL-proficient analytics engineers who want version-controlled, testable transformation workflows with built-in lineage and observability may find dbt Cloud's focused approach more productive than Matillion's combined ETL/ELT platform. Note that dbt Cloud requires a separate ingestion tool, so it is best evaluated as part of a modular data stack rather than a standalone Matillion replacement.
Move to AWS Glue if your organization is deeply invested in the AWS ecosystem and wants to consolidate data integration within your existing cloud provider. AWS Glue's serverless model and native AWS service integration can simplify architecture for AWS-centric environments, and the pay-per-use pricing may be more predictable for intermittent or variable workloads compared to Matillion's credit-based consumption model.
Consider Confluent if your use cases demand real-time or near-real-time data movement that batch-oriented tools cannot deliver. , so teams building event-driven architectures, real-time analytics dashboards, or operational data pipelines will find Confluent's streaming-native approach addresses latency requirements that Matillion and most other batch ELT tools cannot meet.
Stick with Matillion if your team benefits from a unified platform that combines visual low-code pipeline design with SQL and Python support, and your primary data destinations are major cloud warehouses. Matillion's pushdown architecture, native warehouse integration, and support for mixed-skill teams remain strong differentiators for organizations that want a single platform spanning extraction, transformation, and orchestration without assembling a multi-tool stack.
Migration Considerations
When migrating away from Matillion, begin by inventorying your existing Matillion jobs, including orchestration workflows, transformation logic, shared variables, and environment configurations. Matillion's visual designer stores pipeline logic in its own proprietary format, so there is no direct export path to other platforms. Teams should document all transformation SQL and business logic separately before beginning migration, paying special attention to Matillion-specific components like warehouse-native functions and custom variables.
For moves to Airbyte or Fivetran, focus first on replicating your data sources and connectors. Both platforms offer extensive connector libraries that likely cover your existing Matillion data sources, including common integrations like Salesforce, PostgreSQL, MySQL, and cloud storage services. Map each Matillion source component to the equivalent connector in the target platform, and validate data completeness and accuracy after initial replication runs. Transformation logic that lived in Matillion will need to be rebuilt in a tool like dbt if the target platform does not include transformation capabilities.
Migrating to dbt Cloud requires extracting all transformation SQL from your Matillion jobs and restructuring it into dbt models with proper dependencies, tests, and documentation. This is often an opportunity to improve transformation quality through dbt's testing framework, modular design patterns, and data lineage capabilities, but it requires dedicated engineering time to refactor visual pipeline logic into SQL-based models with proper ref() dependencies.
For AWS Glue migrations, leverage the AWS Glue Data Catalog to discover and catalog your data sources. Matillion's visual transformations can be recreated as Glue ETL jobs using either the visual editor or PySpark scripts. Consider running Matillion and the target platform in parallel during the transition to validate data consistency before performing a full cutover.
Regardless of the target platform, plan for a parallel running period where both old and new pipelines operate simultaneously. Compare outputs from both systems to verify data accuracy and completeness. Budget additional time for rebuilding custom transformations, testing data quality, updating downstream dashboards and reports that depend on your pipeline outputs, and retraining team members on the new platform's workflows and interfaces.