Decision comparison
Datafold vs Monte Carlo
Datafold and Monte Carlo address different aspects of the data quality landscape. Datafold specializes in data migration automation and proactive data testing during development, while Monte Carlo focuses on continuous data observability and incident management in production. Organizations choosing between these platforms should consider whether their primary challenge is migrating data platforms and validating data changes during development, or monitoring data health and detecting anomalies across production pipelines.
Architecture choice. These take different approaches to the same problem. Read the table as a fit question rather than a feature race.
These are different kinds of product — Data Validation Framework and Data Observability.
Quick Comparison
| Decision factor | Datafold | Monte Carlo |
|---|---|---|
| Best For | Data teams needing automated data migration, CI/CD data testing, and value-level validation across platforms | Enterprise teams needing end-to-end data and AI observability across their entire data stack |
| Architecture | AI-powered platform with Migration Agent, Data Knowledge Graph, SQL Proxy, and MCP integrations | SaaS platform with deep integrations across ingestion, warehouses, BI, and AI agents |
| Pricing Model | Quote-based. Datafold publishes no prices; its pricing page directs buyers to contact sales. A quote is driven by data sources, data volume, and deployment model, with managed cloud and self-hosted options. The Migration Agent is sold at a fixed price per engagement. | Monte Carlo publishes no amounts. Its tiers are Start, Scale, Enterprise and Business Critical, purchased as credits, and all are quote-only. Every tier includes agent, ML and data observability. |
| Ease of Use | Full-service migration delivery with zero overhead from customer teams; AI agents handle execution | Fast out-of-the-box setup with automatic baseline monitoring and agentic monitor creation |
| Scalability | Handles 5,000+ table migrations; supports any source-to-target combination at enterprise scale | Designed for large enterprises with unlimited users on Scale tier and above; up to 100,000 API calls/day |
| Community/Support | Open-source Data Diff tool (2,988 GitHub stars); full-service delivery with dedicated engineering oversight | Self-guided onboarding on Start tier; expert-guided onboarding with 4-8 hour SLA on higher tiers |
Datafold
- Best For:
- Data teams needing automated data migration, CI/CD data testing, and value-level validation across platforms
- Architecture:
- AI-powered platform with Migration Agent, Data Knowledge Graph, SQL Proxy, and MCP integrations
- Pricing Model:
- Quote-based. Datafold publishes no prices; its pricing page directs buyers to contact sales. A quote is driven by data sources, data volume, and deployment model, with managed cloud and self-hosted options. The Migration Agent is sold at a fixed price per engagement.
- Ease of Use:
- Full-service migration delivery with zero overhead from customer teams; AI agents handle execution
- Scalability:
- Handles 5,000+ table migrations; supports any source-to-target combination at enterprise scale
- Community/Support:
- Open-source Data Diff tool (2,988 GitHub stars); full-service delivery with dedicated engineering oversight
Monte Carlo
- Best For:
- Enterprise teams needing end-to-end data and AI observability across their entire data stack
- Architecture:
- SaaS platform with deep integrations across ingestion, warehouses, BI, and AI agents
- Pricing Model:
- Monte Carlo publishes no amounts. Its tiers are Start, Scale, Enterprise and Business Critical, purchased as credits, and all are quote-only. Every tier includes agent, ML and data observability.
- Ease of Use:
- Fast out-of-the-box setup with automatic baseline monitoring and agentic monitor creation
- Scalability:
- Designed for large enterprises with unlimited users on Scale tier and above; up to 100,000 API calls/day
- Community/Support:
- Self-guided onboarding on Start tier; expert-guided onboarding with 4-8 hour SLA on higher tiers
Public signals
Verified factual signals only. Bars appear only for like-for-like metrics with five weekly assessments for every tool; missing evidence stays explicit. These signals do not establish enterprise adoption, product quality, or total cost.
| Metric | Datafold | Monte Carlo |
|---|---|---|
| Search interest(Market interest) | Unavailable | 0 |
| Product Hunt comments(Community interest) | 7 | Not available |
| Product Hunt reviews(Community interest) | 0 | Not available |
| Product Hunt votes(Community interest) | 17 | Not available |
| PyPI weekly downloads(Developer adoption) | 12.1k | 41.2k |
| GitHub commits, 90d(Developer adoption) | Not available | 231 |
| GitHub stars(Developer adoption) | Not available | 2 |
| Hacker News mentions, 90d(Community interest) | Not available | 0 |
As of September 21, 2026 — updated weekly.
Health & risk evidence
Observed public-source checks for mapped package versions and repositories.
Datafold
September 21, 2026Package vulnerabilities
PyPI · datafold-sdk@0.4.1
0 vulnerabilities
across 1 package
Repository security score
Not available
Monte Carlo
September 21, 2026Package vulnerabilities
PyPI · montecarlodata@0.175.0
0 vulnerabilities
across 1 package
Repository security score
Not available
Interface Preview
Datafold
Monte Carlo
Feature Comparison
| Feature | Datafold | Monte Carlo |
|---|---|---|
| Data Quality Monitoring | ||
| Anomaly Detection | Value-level data validation and comparison via Data Diff across all rows and columns | ML-driven anomaly detection with automatic baselines for freshness, volume, and schema |
| CI/CD Integration | Automated data quality testing integrated into CI/CD pipelines to prevent bad deploys | YAML-based CI/CD configurations for monitor deployment and activation |
| Schema Change Detection | Schema change detection through Data Diff comparisons during migrations and development | Automatic schema change detection with immediate alerts across monitored tables |
| Data Migration | ||
| Migration Automation | Full-service AI-powered migration with automated planning, translation, validation, and delivery | Not a migration tool; monitors data quality during and after migrations |
| SQL Dialect Translation | AI-powered SQL dialect conversion across any source-to-target combination | Not applicable; focused on monitoring rather than code translation |
| Value-Level Validation | Compares data across all rows and columns at any scale to ensure 100% migration parity | Monitors data quality metrics but does not perform row-level data comparison |
| Observability and Lineage | ||
| Data Lineage | Column-level lineage mapping via Data Knowledge Graph for migration complexity assessment | End-to-end column-level lineage across the full data stack with visual tracking |
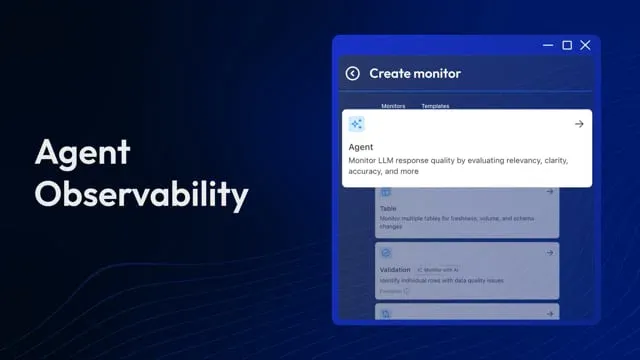
| AI/Agent Observability | Data Knowledge Graph provides context to AI coding agents via MCP for reliable output | Dedicated agent observability for monitoring AI inputs and outputs in production |
| Root Cause Analysis | Automated discrepancy detection with agent-driven correction during migrations | Automated root cause analysis with enriched lineage context and incident management |
| Platform and Cost Optimization | ||
| Cost Management | SQL Proxy routes queries to most cost-efficient compute; up to 80% cost reduction reported | Performance monitoring with financial operations insights and cost attribution on Enterprise tier |
| Alerting | Real-time anomaly detection and monitoring alerts for data quality issues | Granular routing with automated lineage grouping and contextual notifications |
| Impact Analysis | Data Knowledge Graph maps dependencies to assess impact of pipeline changes | Dashboard and downstream system impact assessment with comprehensive analysis |
| Security and Deployment | ||
| Deployment Options | Single-tenant VPC deployment in AWS, GCP, or Azure; governed LLM inference in customer cloud | SaaS with self-hosted storage option on Scale+; enterprise multi-workspace support |
| Compliance | SOC 2 Type 2 and HIPAA compliance; data never leaves customer security perimeter | SSO, SCIM, PII filtering, audit logging; ServiceNow integration on Enterprise tier |
| Open Source | Open-source Data Diff tool (MIT license, 2,988 GitHub stars, Python) | Proprietary SaaS platform with no open-source components |
Data Quality Monitoring
Anomaly Detection
CI/CD Integration
Schema Change Detection
Data Migration
Migration Automation
SQL Dialect Translation
Value-Level Validation
Observability and Lineage
Data Lineage
AI/Agent Observability
Root Cause Analysis
Platform and Cost Optimization
Cost Management
Alerting
Impact Analysis
Security and Deployment
Deployment Options
Compliance
Open Source
Which approach fits
Datafold and Monte Carlo address different aspects of the data quality landscape. Datafold specializes in data migration automation and proactive data testing during development, while Monte Carlo focuses on continuous data observability and incident management in production. Organizations choosing between these platforms should consider whether their primary challenge is migrating data platforms and validating data changes during development, or monitoring data health and detecting anomalies across production pipelines.
When each approach fits
Choose Datafold if:
Data platform migrations, CI/CD data testing, and proactive data validation during development
Choose Monte Carlo if:
Continuous data and AI observability across production data pipelines at enterprise scale
These scenarios reflect the available product evidence. Your requirements, existing stack, and team expertise should guide the final decision.
Frequently Asked Questions
What is the main difference between Datafold and Monte Carlo?
Datafold specializes in data migration automation and proactive data testing during development, with AI-powered code translation and value-level validation. Monte Carlo focuses on continuous data observability and incident management in production, using ML-driven anomaly detection across your entire data stack. They address different phases of the data lifecycle and can be complementary.
How do Datafold and Monte Carlo compare on pricing?
Datafold uses custom pricing based on data sources, volume, and deployment model, with mid-market annual contracts typically in the a quoted amount range according to third-party data. Monte Carlo uses a tiered credit-based consumption model across Start, Scale, Enterprise, and Business Critical tiers. Both require contacting sales for specific quotes, and both offer volume-based pricing rather than per-seat licensing.
Can Datafold and Monte Carlo be used together?
Yes, Datafold and Monte Carlo address different aspects of data quality. Datafold excels at migration-time validation and CI/CD data testing to prevent bad deploys, while Monte Carlo provides continuous production monitoring and anomaly detection. Organizations with both migration and ongoing observability needs may benefit from using both platforms.
Does Datafold have any open-source components?
Yes, Datafold maintains Data Diff, an open-source tool for comparing tables within or across databases. It has 2,988 GitHub stars, is written in Python, and is available under the MIT license. The open-source tool supports databases including Snowflake, PostgreSQL, MySQL, Databricks SQL, Oracle, and Trino.
Which platform is better for AI agent reliability?
Both platforms address AI reliability from different angles. Datafold provides a Data Knowledge Graph that serves context to AI coding agents via MCP, helping them produce reliable output during development. Monte Carlo offers dedicated agent observability for monitoring AI inputs and outputs in production, with the ability to trace and troubleshoot enterprise agents. Datafold focuses on the development side while Monte Carlo covers production monitoring.