Decision comparison
Anomalo vs Monte Carlo
Anomalo and Monte Carlo both address data quality and observability for enterprise teams, but they approach the problem from different angles. Anomalo is an AI-first data quality platform that uses unsupervised machine learning to automatically detect anomalies across structured, semi-structured, and unstructured data without manual rule configuration. Monte Carlo is an end-to-end data and AI observability platform that provides comprehensive monitoring from ingestion through consumption, including dedicated agent observability for AI systems in production. The right choice depends on whether your primary need is automated data quality detection with minimal setup or full-stack observability with lineage-driven incident management across your entire data and AI ecosystem.
Direct comparison. These are reviewed substitutes bought for the same job, so the differences below are the ones that decide between them.
All 2 are data observability.
Quick Comparison
| Decision factor | Anomalo | Monte Carlo |
|---|---|---|
| Best For | Enterprises needing automated data quality monitoring across structured and unstructured data | Enterprise teams needing end-to-end data and AI observability from ingestion to consumption |
| Core Approach | AI-first data quality with unsupervised ML that learns patterns per dataset | Full-stack data and AI observability with lineage, alerting, and incident management |
| Pricing Model | Contact for pricing | Monte Carlo publishes no amounts. Its tiers are Start, Scale, Enterprise and Business Critical, purchased as credits, and all are quote-only. Every tier includes agent, ML and data observability. |
| AI/ML Capabilities | Unsupervised ML models built per dataset; agentic platform with nine specialized agents | ML-driven anomaly detection; AI-powered monitoring agents; agent observability for LLM apps |
| Deployment | SaaS with in-VPC deployment option | SaaS with self-hosted storage option on Scale tier and above |
| Unstructured Data Support | Yes, monitors documents and unstructured data alongside structured tables | Yes, AI-powered checks for unstructured fields in Snowflake, Databricks, and BigQuery |
Anomalo
- Best For:
- Enterprises needing automated data quality monitoring across structured and unstructured data
- Core Approach:
- AI-first data quality with unsupervised ML that learns patterns per dataset
- Pricing Model:
- Contact for pricing
- AI/ML Capabilities:
- Unsupervised ML models built per dataset; agentic platform with nine specialized agents
- Deployment:
- SaaS with in-VPC deployment option
- Unstructured Data Support:
- Yes, monitors documents and unstructured data alongside structured tables
Monte Carlo
- Best For:
- Enterprise teams needing end-to-end data and AI observability from ingestion to consumption
- Core Approach:
- Full-stack data and AI observability with lineage, alerting, and incident management
- Pricing Model:
- Monte Carlo publishes no amounts. Its tiers are Start, Scale, Enterprise and Business Critical, purchased as credits, and all are quote-only. Every tier includes agent, ML and data observability.
- AI/ML Capabilities:
- ML-driven anomaly detection; AI-powered monitoring agents; agent observability for LLM apps
- Deployment:
- SaaS with self-hosted storage option on Scale tier and above
- Unstructured Data Support:
- Yes, AI-powered checks for unstructured fields in Snowflake, Databricks, and BigQuery
Public signals
Verified factual signals only. Bars appear only for like-for-like metrics with five weekly assessments for every tool; missing evidence stays explicit. These signals do not establish enterprise adoption, product quality, or total cost.
| Metric | Anomalo | Monte Carlo |
|---|---|---|
| Search interest(Market interest) | Unavailable | 0 |
| Product Hunt comments(Community interest) | 21 | Not available |
| Product Hunt reviews(Community interest) | 0 | Not available |
| Product Hunt votes(Community interest) | 292 | Not available |
| PyPI weekly downloads(Developer adoption) | 25.4k | 46.0k |
| GitHub commits, 90d(Developer adoption) | Not available | 205 |
| GitHub stars(Developer adoption) | Not available | 2 |
| Hacker News mentions, 90d(Community interest) | Not available | 0 |
As of October 5, 2026 — updated weekly.
Health & risk evidence
Observed public-source checks for mapped package versions and repositories.
Anomalo
October 5, 2026Package vulnerabilities
PyPI · anomalo@0.52.5
0 vulnerabilities
across 1 package
Repository security score
Not available
Monte Carlo
October 5, 2026Package vulnerabilities
PyPI · montecarlodata@0.176.0
0 vulnerabilities
across 1 package
Repository security score
Not available
Interface Preview
Monte Carlo
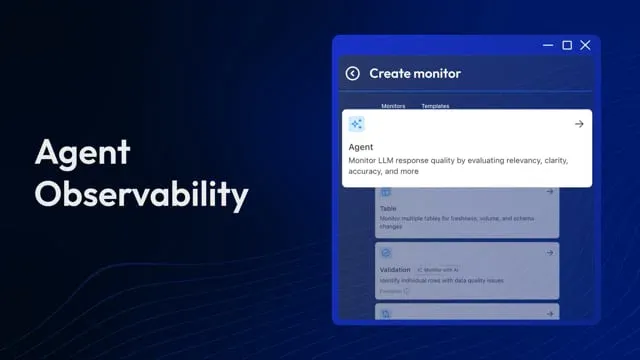
Feature Comparison
| Feature | Anomalo | Monte Carlo |
|---|---|---|
| Data Quality Monitoring | ||
| Automated Anomaly Detection | Unsupervised ML models built per dataset learn historical patterns and detect statistically significant deviations without manual thresholds | ML-driven anomaly detection with automatic baseline coverage for freshness, volume, and schema; AI-powered rules and data profiling |
| Custom Validation Rules | No-code UI for business rules and KPIs; supports SQL checks and API-based rule migration | SQL monitors, codeless UI, YAML-based CI/CD configurations, and AI-powered monitor creation through natural language |
| Data Profiling | Visual data profiling with distribution analysis for each column; rich visualizations for check pass/fail analysis | Automatic data profiling integrated into monitoring; metric quality checks for unstructured and structured fields |
| Observability & Lineage | ||
| Data Lineage | Upstream and downstream lineage pulled directly from data warehouse or lakehouse for each monitored table | End-to-end column-level lineage across the entire data ecosystem with visual lineage tracking |
| Impact Analysis | Lineage-based dependency mapping; focused on data quality impact within the warehouse layer | Comprehensive impact analysis for downstream dashboards, pipelines, and business processes with automated lineage grouping |
| Root Cause Analysis | Automated root cause analysis with data lineage tools for rapid issue resolution within monitored tables | Lineage-enriched root cause analysis that correlates anomalies across systems; AI agents for troubleshooting and incident triage |
| AI & Agentic Capabilities | ||
| AI Agents | Nine-agent agentic platform including Table Observability, Data Quality Rules, Proactive Insights, Conversational Analytics (AIDA), and more | Fleet of agents for monitor creation, troubleshooting, root cause analysis, and automated coverage recommendations |
| AI/Agent Observability | Not a primary focus; agents operate on data quality and insights, not on monitoring external AI systems | Dedicated Agent Observability product to monitor AI inputs and outputs from source to agent in production |
| Natural Language Interface | AIDA conversational analytics agent for querying data in natural language with organizational memory | AI-powered monitoring agent that accepts natural language prompts to create and deploy monitors |
| Integration & Scalability | ||
| Data Warehouse Support | Native integrations with Snowflake, BigQuery, Databricks, and cloud data lakes; backed by Snowflake Ventures and Databricks Ventures | Snowflake, BigQuery, Databricks, plus Oracle, SAP Hana, Teradata, Microsoft Fabric on Enterprise tier |
| Pipeline & BI Integration | Integrations with ETL tools, orchestrators, and cloud data platforms; focused on warehouse-level monitoring | End-to-end integrations from ingestion to consumption including BI tools, Salesforce, Data Cloud, and CI/CD pipelines |
| Alerting & Incident Management | Automated alerts with severity scoring, smart noise reduction, and automated routing | Granular alert routing by owner, team, or domain; automated lineage grouping; integrated incident management workflows |
| Security & Compliance | ||
| Enterprise Security | SOC 2 compliance, role-based access controls, audit trails, and in-VPC deployment | SSO, SCIM, self-hosted storage, PII filtering, audit logging on Scale tier; SOC 2 compliance |
| Deployment Flexibility | SaaS with in-VPC deployment for data-sensitive environments | SaaS with self-hosted storage option; multi-workspace support for testing and development on Enterprise tier |
| API Access | API available for custom integrations, rule migration, and programmatic configuration | 10K API calls/day on Start, 50K on Scale, 100K on Enterprise; webhooks for automation |
Data Quality Monitoring
Automated Anomaly Detection
Custom Validation Rules
Data Profiling
Observability & Lineage
Data Lineage
Impact Analysis
Root Cause Analysis
AI & Agentic Capabilities
AI Agents
AI/Agent Observability
Natural Language Interface
Integration & Scalability
Data Warehouse Support
Pipeline & BI Integration
Alerting & Incident Management
Security & Compliance
Enterprise Security
Deployment Flexibility
API Access
Which to choose
Anomalo and Monte Carlo both address data quality and observability for enterprise teams, but they approach the problem from different angles. Anomalo is an AI-first data quality platform that uses unsupervised machine learning to automatically detect anomalies across structured, semi-structured, and unstructured data without manual rule configuration. Monte Carlo is an end-to-end data and AI observability platform that provides comprehensive monitoring from ingestion through consumption, including dedicated agent observability for AI systems in production. The right choice depends on whether your primary need is automated data quality detection with minimal setup or full-stack observability with lineage-driven incident management across your entire data and AI ecosystem.
Best-fit scenarios
Choose Anomalo if:
Enterprise data teams with large, stable data warehouses who want automated data quality monitoring with minimal manual configuration. Anomalo is particularly strong for organizations that need to monitor both structured and unstructured data using ML-driven detection, prefer a hands-off approach where the platform learns patterns per dataset, and value deep investment backing from Snowflake and Databricks. Choose Anomalo when your primary goal is catching data quality issues before they impact analytics, AI models, or business decisions, and when you want an agentic platform with conversational analytics capabilities.
Choose Monte Carlo if:
Enterprise data and AI teams who need end-to-end observability spanning the full data lifecycle from ingestion to consumption. Monte Carlo is the stronger choice for organizations running AI agents in production that need dedicated agent observability, teams requiring comprehensive impact analysis across downstream dashboards and business processes, and companies that want granular alert routing and incident management workflows. Choose Monte Carlo when you need visibility beyond the warehouse into pipeline health, BI layer reliability, and AI system trustworthiness, and when tiered pricing with a clear entry point matters to your procurement process.
These scenarios reflect the available product evidence. Your requirements, existing stack, and team expertise should guide the final decision.
Frequently Asked Questions
Does Anomalo require writing rules to start monitoring data?
No. Anomalo uses unsupervised machine learning that automatically learns the historical patterns, structure, and distribution of each dataset. Monitoring begins without manual thresholds or rules. We note that you can also add custom validation rules, business KPIs, and SQL checks through the no-code UI or API for tables where you need domain-specific logic.
How does Monte Carlo's pricing model work?
Monte Carlo uses credit-based consumption pricing across four tiers. The Start tier supports up to 10 users with up to 1,000 monitors and 10,000 API calls per day. Scale adds unlimited users, SSO, SCIM, and 50,000 API calls per day. Enterprise includes Oracle, SAP Hana, Teradata, and Microsoft Fabric integrations plus 100,000 API calls per day. Business Critical provides maximum availability for mission-critical environments. You buy credits and consume them based on published consumption rates.
Can both tools monitor unstructured data?
Yes. Anomalo was among the first platforms to extend data quality monitoring to unstructured data, applying the same ML-driven approach to documents and text data. Monte Carlo has also added AI-powered checks for unstructured fields, with support for unstructured file types in Snowflake, Databricks, and BigQuery. Anomalo has a longer track record in this area, while Monte Carlo has recently expanded into it.
Which platform is better for monitoring AI agents in production?
Monte Carlo is the stronger choice for AI agent observability. It offers a dedicated Agent Observability product that monitors AI inputs and outputs from source to agent, traces agent context, performance, behavior, and outputs, and integrates with agents built on Langchain, Snowflake Intelligence, Databricks Genie, and other frameworks. Anomalo's agentic capabilities focus on data quality operations rather than monitoring external AI systems.
Do Anomalo and Monte Carlo integrate with the same data warehouses?
Both platforms support the major cloud data warehouses including Snowflake, BigQuery, and Databricks. Monte Carlo extends further on the Enterprise tier with support for Oracle, SAP Hana, Teradata, and Microsoft Fabric, plus direct integration with Salesforce and Data Cloud. Anomalo has strategic investment partnerships with both Snowflake Ventures and Databricks Ventures, reflecting deep native integrations with those platforms.