Decision comparison
Runcrate vs Together AI
Runcrate and Together AI both sell per-token access to open models and GPUs by the hour, so the choice turns on how much you want managed. Together AI covers the full lifecycle with fixed list prices: provisioned throughput, dedicated endpoints, managed fine-tuning and reserved GPU clusters. Runcrate keeps it simple: one prepaid balance, 127 hosted models and raw GPU machines with a shell at live marketplace rates. On the models both serve, per-token prices can be close or far apart, so check your exact model. We compared both on November 1, 2026 from each vendor's pricing and product pages: per-token rates, GPU rates and terms, fine-tuning, billing and extras.
Direct comparison. These are reviewed substitutes bought for the same job, so the differences below are the ones that decide between them.
All 2 are model hosting platforms.
Quick Comparison
| Decision factor | Runcrate | Together AI |
|---|---|---|
| Best for | Developers and coding agents that want open-model calls and rented GPU machines on one prepaid balance with no monthly fee. Instances come with SSH, Jupyter and VS Code in the browser, and a CLI, SDKs and a remote MCP server let an agent launch and delete a GPU by itself. Pick it for small teams that move between calling a model and running their own code on a GPU, and that do not need a managed fine-tuning service. | Teams that build on open models and want one vendor to cover more of the lifecycle: serverless inference, provisioned throughput, dedicated endpoints, managed fine-tuning and post-training, and GPU clusters. Pick it when you need a managed fine-tuning job, guaranteed capacity for an endpoint, or GPU clusters with published reserved terms. |
| Per-token rates | Per token for language models, per image for most image models and per second for video, across 127 models. On November 1, 2026 it listed MiniMax M3.1 Flash at $0.158 input and $0.63 output per 1M tokens, Kimi K2.6 at $0.788 and $3.68, and DeepSeek V4.1 Flash 1017 at $0.0515 and $0.154 on shared capacity, rising to $0.103 and $0.309 when that capacity is busy. Five open models have a free weekly allowance for a GitHub account at least 30 days old. | Per 1M tokens by model, with separate input, output and cached-input rates, and a separate Batch API price. On October 26, 2026 it listed MiniMax M3.1 Flash at $0.15 input and $0.60 output, DeepSeek V4.1 Flash 1017 at $0.30 and $1.20, Kimi K3 at $3.00 and $15.00, and gpt-oss-120B at $0.15 and $0.60. Provisioned Throughput reserves fixed capacity in throughput units for steady traffic. |
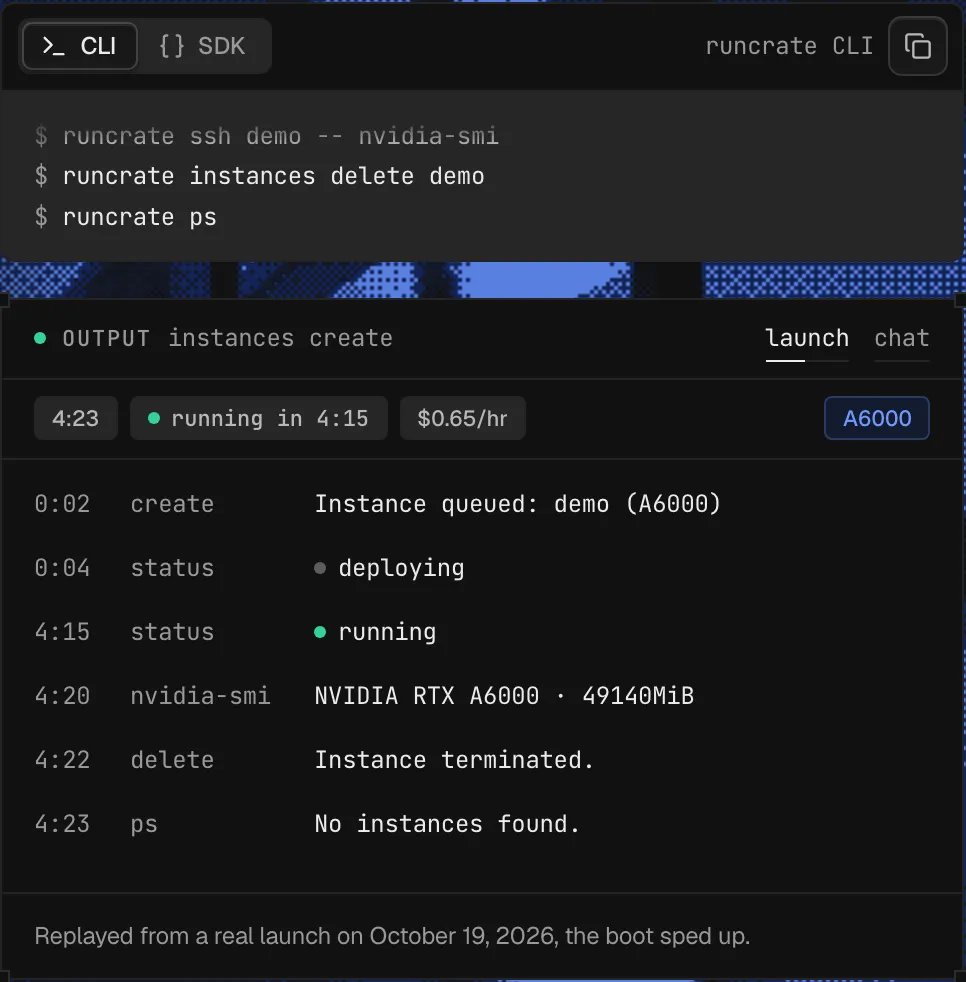
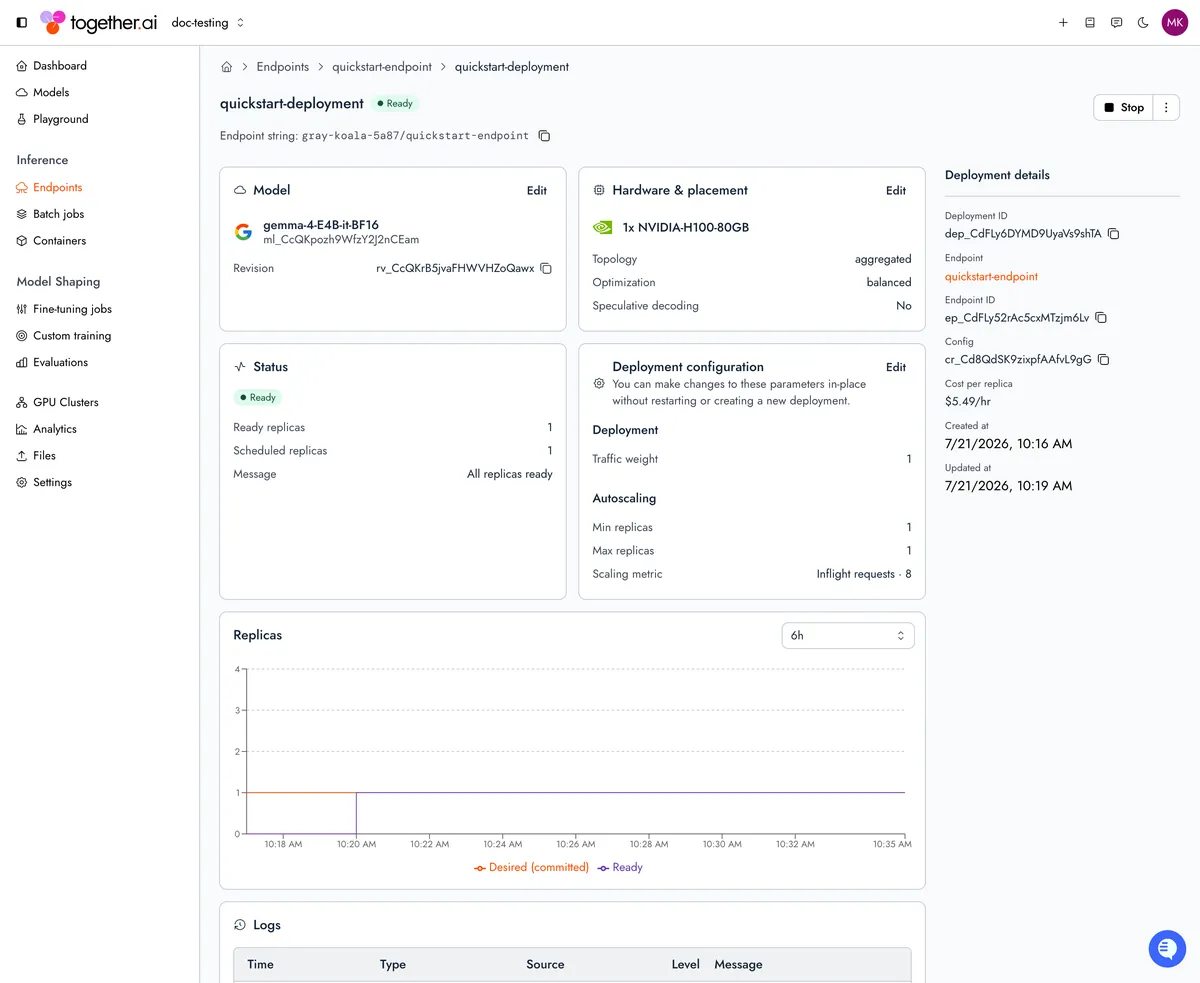
| GPU-hour rates | Live per-GPU-hour rates, refreshed every 5 minutes and billed by the second on most GPUs, from $0.36 per GPU-hour. Runcrate's own example on November 1, 2026: $20 bought 8 hours on one H100. On that day we saw its H100 rate move by about 30% within an hour. Each instance is one machine with a shell; self-serve multi-node clusters and reserved clusters quoted by GPU owners cover larger jobs. | GPU Clusters on demand cost $3.99 per GPU-hour for HGX H100, $5.99 for H200 and $8.19 for B200, with separate preemptible rates and reserved terms from 3 days to 181+ days. Dedicated Inference endpoints cost $5.49 per GPU-hour on H100 and $8.99 on B200. Rates are fixed list prices, so a budget written today holds until Together AI changes its price list. |
| Fine-tuning | Fine-tuning runs on a GPU instance you rent, using Runcrate's ready images for fine-tuning and serving. You choose the framework and run the job yourself, and the instance bills by the second while it runs. To serve the result, you load the weights on an instance and serve them with your own stack. | Managed fine-tuning priced per 1M training tokens: LoRA supervised fine-tuning starts at $0.34 per 1M tokens, with a minimum charge per job from $4.00. Direct preference optimization and full fine-tuning cost more. Post-training runs on HGX B200s, billed per minute for each active model resource. |
| Billing and commitments | One prepaid balance for GPUs, models and storage, with no monthly fee. You add $20 to $10,000 at a time by card, and auto-recharge takes a threshold of $20 to $5,000 and a target of $50 to $10,000. A launch needs $10 or an hour of the machine. Under $1.00, running instances are deleted after a 15-minute warning. A machine can be prepaid for 1 to 12 months at a discount. | Pay as you go for serverless inference, dedicated endpoints and on-demand GPU clusters. Steady workloads can reserve inference capacity through Provisioned Throughput or take reserved GPU cluster terms, and reserved dedicated endpoints and GB200 or GB300 NVL72 systems are arranged with its sales team. |
| Extras on the account | Storage volumes at $0.03 per GB a month that survive instance deletion, auto stop by maximum runtime or idle time, a job mode that stops when its command ends, and a remote MCP server so coding agents can run the whole GPU lifecycle. | Code Sandbox VMs at $0.0446 per vCPU-hour and $0.0149 per GiB of RAM per hour, a Code Interpreter at $0.03 per 60-minute session, and a shared filesystem colocated with compute at $0.16 per GiB a month. |
Runcrate
- Best for:
- Developers and coding agents that want open-model calls and rented GPU machines on one prepaid balance with no monthly fee. Instances come with SSH, Jupyter and VS Code in the browser, and a CLI, SDKs and a remote MCP server let an agent launch and delete a GPU by itself. Pick it for small teams that move between calling a model and running their own code on a GPU, and that do not need a managed fine-tuning service.
- Per-token rates:
- Per token for language models, per image for most image models and per second for video, across 127 models. On November 1, 2026 it listed MiniMax M3.1 Flash at $0.158 input and $0.63 output per 1M tokens, Kimi K2.6 at $0.788 and $3.68, and DeepSeek V4.1 Flash 1017 at $0.0515 and $0.154 on shared capacity, rising to $0.103 and $0.309 when that capacity is busy. Five open models have a free weekly allowance for a GitHub account at least 30 days old.
- GPU-hour rates:
- Live per-GPU-hour rates, refreshed every 5 minutes and billed by the second on most GPUs, from $0.36 per GPU-hour. Runcrate's own example on November 1, 2026: $20 bought 8 hours on one H100. On that day we saw its H100 rate move by about 30% within an hour. Each instance is one machine with a shell; self-serve multi-node clusters and reserved clusters quoted by GPU owners cover larger jobs.
- Fine-tuning:
- Fine-tuning runs on a GPU instance you rent, using Runcrate's ready images for fine-tuning and serving. You choose the framework and run the job yourself, and the instance bills by the second while it runs. To serve the result, you load the weights on an instance and serve them with your own stack.
- Billing and commitments:
- One prepaid balance for GPUs, models and storage, with no monthly fee. You add $20 to $10,000 at a time by card, and auto-recharge takes a threshold of $20 to $5,000 and a target of $50 to $10,000. A launch needs $10 or an hour of the machine. Under $1.00, running instances are deleted after a 15-minute warning. A machine can be prepaid for 1 to 12 months at a discount.
- Extras on the account:
- Storage volumes at $0.03 per GB a month that survive instance deletion, auto stop by maximum runtime or idle time, a job mode that stops when its command ends, and a remote MCP server so coding agents can run the whole GPU lifecycle.
Together AI
- Best for:
- Teams that build on open models and want one vendor to cover more of the lifecycle: serverless inference, provisioned throughput, dedicated endpoints, managed fine-tuning and post-training, and GPU clusters. Pick it when you need a managed fine-tuning job, guaranteed capacity for an endpoint, or GPU clusters with published reserved terms.
- Per-token rates:
- Per 1M tokens by model, with separate input, output and cached-input rates, and a separate Batch API price. On October 26, 2026 it listed MiniMax M3.1 Flash at $0.15 input and $0.60 output, DeepSeek V4.1 Flash 1017 at $0.30 and $1.20, Kimi K3 at $3.00 and $15.00, and gpt-oss-120B at $0.15 and $0.60. Provisioned Throughput reserves fixed capacity in throughput units for steady traffic.
- GPU-hour rates:
- GPU Clusters on demand cost $3.99 per GPU-hour for HGX H100, $5.99 for H200 and $8.19 for B200, with separate preemptible rates and reserved terms from 3 days to 181+ days. Dedicated Inference endpoints cost $5.49 per GPU-hour on H100 and $8.99 on B200. Rates are fixed list prices, so a budget written today holds until Together AI changes its price list.
- Fine-tuning:
- Managed fine-tuning priced per 1M training tokens: LoRA supervised fine-tuning starts at $0.34 per 1M tokens, with a minimum charge per job from $4.00. Direct preference optimization and full fine-tuning cost more. Post-training runs on HGX B200s, billed per minute for each active model resource.
- Billing and commitments:
- Pay as you go for serverless inference, dedicated endpoints and on-demand GPU clusters. Steady workloads can reserve inference capacity through Provisioned Throughput or take reserved GPU cluster terms, and reserved dedicated endpoints and GB200 or GB300 NVL72 systems are arranged with its sales team.
- Extras on the account:
- Code Sandbox VMs at $0.0446 per vCPU-hour and $0.0149 per GiB of RAM per hour, a Code Interpreter at $0.03 per 60-minute session, and a shared filesystem colocated with compute at $0.16 per GiB a month.
Public signals
Verified factual signals only. Bars appear only for like-for-like metrics with five weekly assessments for every tool; missing evidence stays explicit. These signals do not establish enterprise adoption, product quality, or total cost.
| Metric | Runcrate | Together AI |
|---|---|---|
| GitHub commits, 90d(Developer adoption) | 16 | 339 |
| GitHub stars(Developer adoption) | 2 | 12 |
| Search interest(Market interest) | Unavailable | 10 |
| Hacker News mentions, 90d(Community interest) | 0 | 3 |
| npm weekly downloads(Developer adoption) | 52 | 99.1k |
| PyPI weekly downloads(Developer adoption) | 36 | 437.6k |
| Hugging Face downloads(Product adoption) | Not available | 27.1k |
| Hugging Face likes(Product adoption) | Not available | 2.3k |
As of November 9, 2026 — updated weekly.
Health & risk evidence
Observed public-source checks for mapped package versions and repositories.
Runcrate
November 9, 2026Package vulnerabilities
npm · @runcrate/sdk@0.5.0 · PyPI · runcrate-sdk@0.5.0
0 vulnerabilities
across 2 packages
Repository security score
Not available
Together AI
November 9, 2026Package vulnerabilities
PyPI · together@3.1.1 · npm · together-ai@1.0.0
0 vulnerabilities
across 2 packages
Repository security score
Not available
Interface Preview
Runcrate
Together AI
Feature Comparison
| Feature | Runcrate | Together AI |
|---|---|---|
| Inference | ||
| API format | OpenAI-compatible, base URL api.runcrate.ai/v1 | Serverless API priced per 1M tokens, with a Batch API |
| Catalogue | 127 models across text, vision, image, video and audio | Chat, vision, image, audio, video, transcription, embeddings, rerank and moderation models |
| MiniMax M3.1 Flash | $0.158 input, $0.63 output per 1M tokens (November 1, 2026) | $0.15 input, $0.60 output per 1M tokens (October 26, 2026) |
| Steady-traffic option | Price a large inference volume for a term with Runcrate's engineers | Provisioned Throughput in fixed throughput units |
| Dedicated endpoints | Serve your own weights on a rented instance | $5.49 per GPU-hour on H100, $8.99 on B200 |
| GPU compute | ||
| What you rent | One instance with SSH, Jupyter and VS Code in the browser | GPU clusters billed per GPU-hour |
| H100 on demand | Live rate; $20 bought 8 hours on November 1, 2026 | $3.99 per GPU-hour |
| Price changes | Live rates refreshed every 5 minutes | Fixed list rates |
| Commitments | Prepay a machine 1 to 12 months; reserved clusters quoted by GPU owners | Reserved cluster terms from 3 days to 181+ days |
| Storage | $0.03 per GB a month | Shared filesystem at $0.16 per GiB a month |
| Training and billing | ||
| Fine-tuning | On your own rented GPU, with ready fine-tuning images | Managed LoRA from $0.34 per 1M tokens, minimum from $4.00 per job |
| Payment | Prepaid balance, $20 to $10,000 per top-up, with auto-recharge | Pay as you go |
| Agent tooling | CLI, Python and TypeScript SDKs, remote MCP server | Code Sandbox and Code Interpreter |
Inference
API format
Catalogue
MiniMax M3.1 Flash
Steady-traffic option
Dedicated endpoints
GPU compute
What you rent
H100 on demand
Price changes
Commitments
Storage
Training and billing
Fine-tuning
Payment
Agent tooling
Which to choose
Runcrate and Together AI both sell per-token access to open models and GPUs by the hour, so the choice turns on how much you want managed. Together AI covers the full lifecycle with fixed list prices: provisioned throughput, dedicated endpoints, managed fine-tuning and reserved GPU clusters. Runcrate keeps it simple: one prepaid balance, 127 hosted models and raw GPU machines with a shell at live marketplace rates. On the models both serve, per-token prices can be close or far apart, so check your exact model. We compared both on November 1, 2026 from each vendor's pricing and product pages: per-token rates, GPU rates and terms, fine-tuning, billing and extras.
Best-fit scenarios
Choose Runcrate if:
Choose Runcrate when one developer or coding agent switches between calling hosted models and running its own code on a GPU, and wants one prepaid balance with no monthly fee. On November 1, 2026 its own example put 8 hours on one H100 at $20, and DeepSeek V4.1 Flash 1017 was $0.0515 input per 1M tokens on shared capacity, against $0.30 on Together AI. The CLI, SDKs and MCP server let an agent launch and delete a GPU by itself. Together AI loses here on simplicity: it splits GPUs into clusters and dedicated endpoints with separate prices. Runcrate is the weaker fit when you need managed fine-tuning, an endpoint someone else runs, or a price that will not move between the quote and the invoice.
Choose Together AI if:
Choose Together AI when the team wants the vendor to run more of the work: managed LoRA fine-tuning from $0.34 per 1M tokens, dedicated inference endpoints at $5.49 per GPU-hour on H100, Provisioned Throughput for steady traffic, and reserved GPU clusters with published terms. Its rates are fixed list prices, so a budget holds. Runcrate loses here because fine-tuning and custom serving mean running your own server on a rented instance, and its live GPU rates can move during the day. Together AI is the weaker fit for an agent that wants a plain Linux machine with SSH on a small prepaid balance.
These scenarios reflect the available product evidence. Your requirements, existing stack, and team expertise should guide the final decision.
Frequently Asked Questions
Is the same model priced the same on Runcrate and Together AI?
Not always. MiniMax M3.1 Flash was $0.158 input and $0.63 output per 1M tokens on Runcrate on November 1, 2026, and $0.15 and $0.60 on Together AI on October 26, 2026. DeepSeek V4.1 Flash 1017 was $0.0515 and $0.154 on Runcrate's shared capacity, or $0.103 and $0.309 when busy, against $0.30 and $1.20 on Together AI. Price your exact model on the day you buy.
What does an H100 hour cost on each?
Together AI lists $3.99 per GPU-hour for an on-demand H100 in GPU Clusters, and $5.49 for an H100 behind a Dedicated Inference endpoint. Runcrate's H100 rate is live: its own example on November 1, 2026 put 8 hours at $20, and we saw the rate move by about 30% within an hour that day.
Where should I fine-tune a model?
On Together AI, if you want a managed job: LoRA supervised fine-tuning starts at $0.34 per 1M tokens, with a minimum charge per job from $4.00. On Runcrate you rent a GPU, use a ready fine-tuning image and run the job yourself, paying by the second for the instance.
Can I reserve capacity on each?
Together AI publishes reserved GPU cluster terms from 3 days to 181+ days and sells Provisioned Throughput for inference. Runcrate lets you prepay a machine for 1 to 12 months at a discount, and quotes reserved multi-node clusters of a month or longer from GPU owners after checking your company and your need.