Decision comparison
Sigma Computing vs ThoughtSpot
Sigma and ThoughtSpot both try to remove an intermediary, and they remove different ones. Sigma removes the export: a spreadsheet grid over the warehouse where every action compiles to SQL, so people work the way they already do without copying data out. ThoughtSpot removes the ticket: a search box over a governed model so questions do not queue behind an analyst.
Direct comparison. These are reviewed substitutes bought for the same job, so the differences below are the ones that decide between them.
All 2 are BI platforms.
Quick Comparison
| Decision factor | Sigma Computing | ThoughtSpot |
|---|---|---|
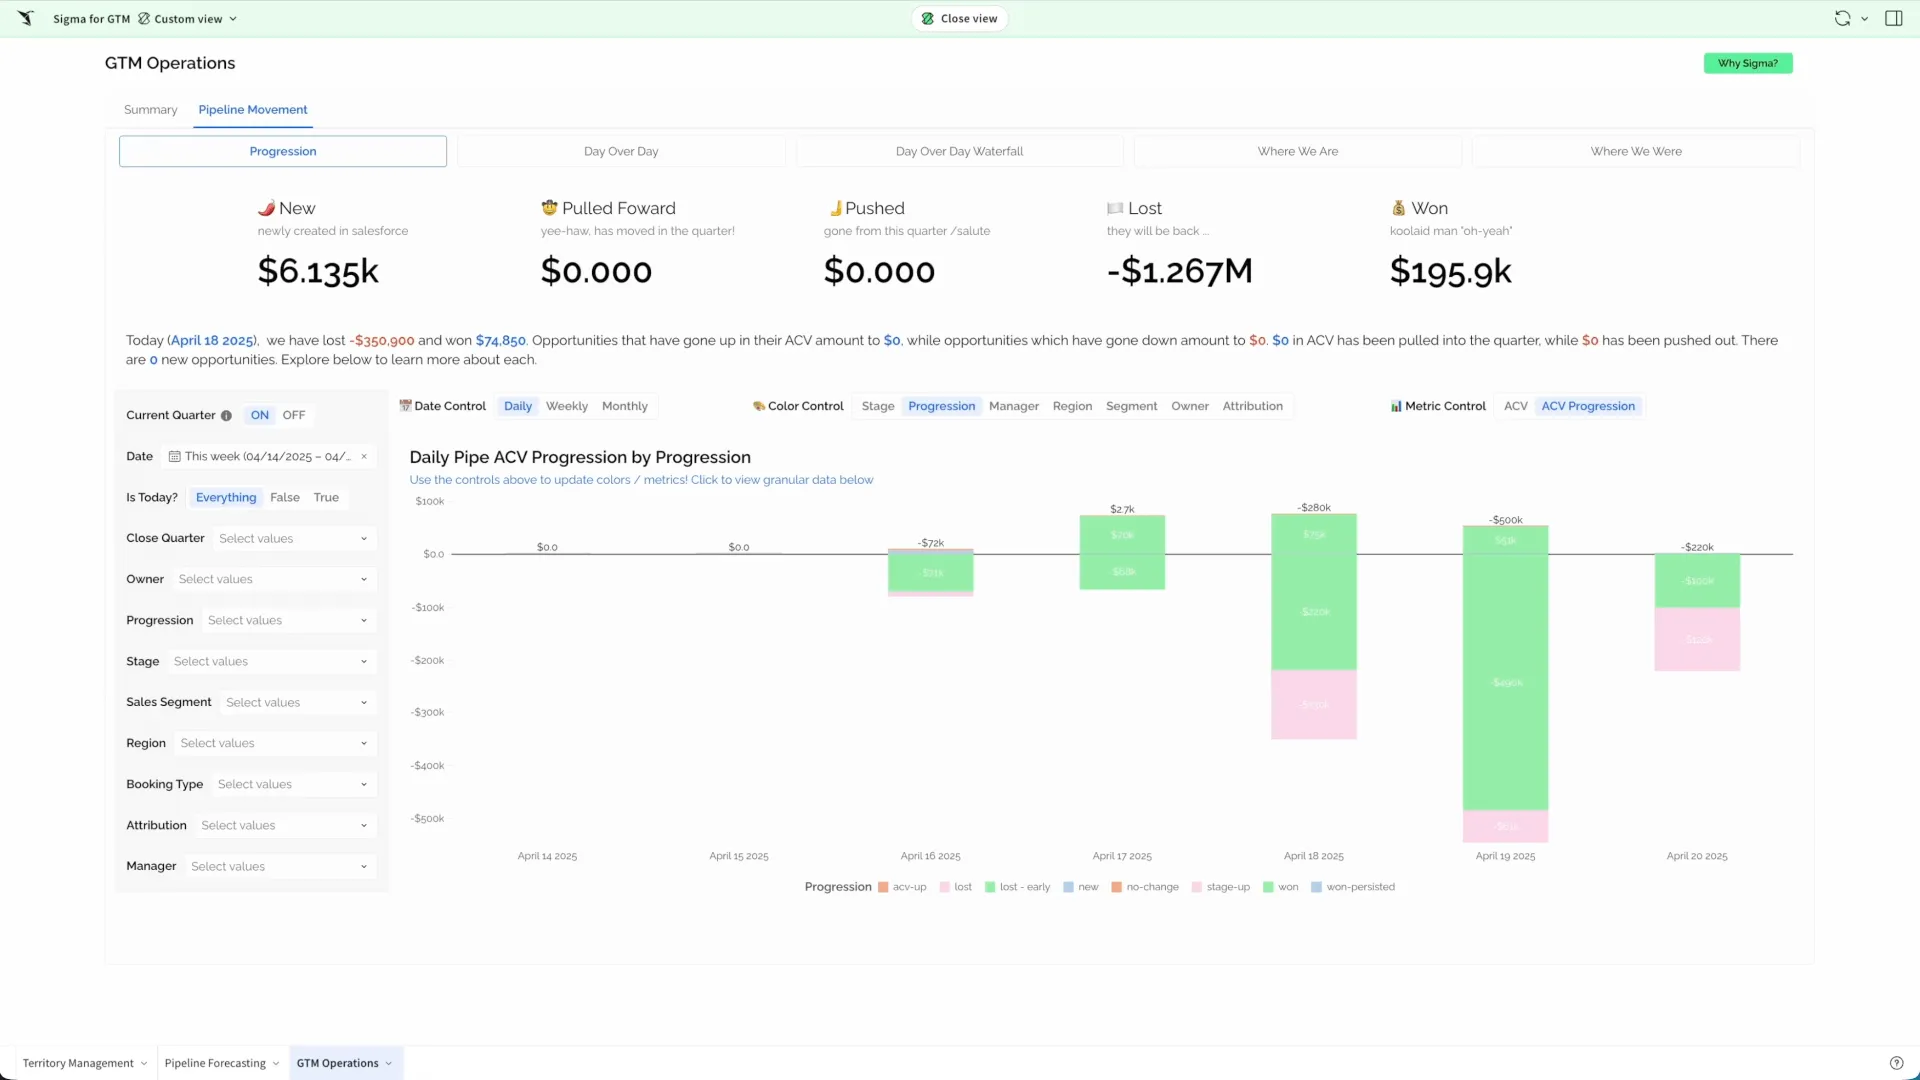
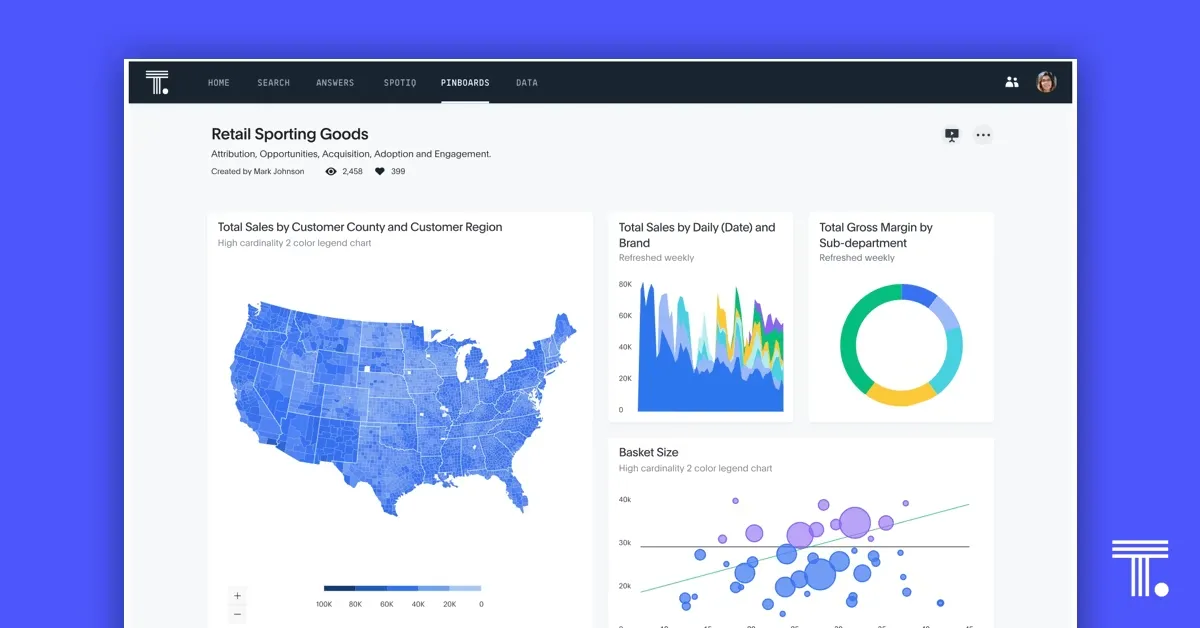
| What it is | A spreadsheet-native interface over the warehouse, where analysts work in familiar rows and columns and every action becomes SQL | An analytics platform where the primary interface is a search box, aimed at business users asking their own questions |
| Primary interface | A spreadsheet grid over the warehouse, where every action becomes SQL | A search box over a governed model |
| Who it is for | Analysts and business users who already work in spreadsheets | Business users who want to ask a question in words |
| Query pattern | Live SQL against the warehouse; no extract to refresh | Live querying against the warehouse, with caching for responsiveness |
| What it replaces | The export to a spreadsheet, and the stale file that follows | The ticket filed with the data team |
| Prerequisite | A warehouse with tables people can work against | A modelled, well-named dataset the search interface can interpret |
| Best fit | Organisations where everyone exports to a spreadsheet to do real work | Organisations where everyone waits on an analyst |
| Connectivity | Connects to Snowflake, BigQuery, Redshift and Databricks over standard drivers, with REST APIs for automation | Connects to Snowflake, BigQuery, Redshift and Databricks over standard drivers, with REST APIs for automation |
Sigma Computing
- What it is:
- A spreadsheet-native interface over the warehouse, where analysts work in familiar rows and columns and every action becomes SQL
- Primary interface:
- A spreadsheet grid over the warehouse, where every action becomes SQL
- Who it is for:
- Analysts and business users who already work in spreadsheets
- Query pattern:
- Live SQL against the warehouse; no extract to refresh
- What it replaces:
- The export to a spreadsheet, and the stale file that follows
- Prerequisite:
- A warehouse with tables people can work against
- Best fit:
- Organisations where everyone exports to a spreadsheet to do real work
- Connectivity:
- Connects to Snowflake, BigQuery, Redshift and Databricks over standard drivers, with REST APIs for automation
ThoughtSpot
- What it is:
- An analytics platform where the primary interface is a search box, aimed at business users asking their own questions
- Primary interface:
- A search box over a governed model
- Who it is for:
- Business users who want to ask a question in words
- Query pattern:
- Live querying against the warehouse, with caching for responsiveness
- What it replaces:
- The ticket filed with the data team
- Prerequisite:
- A modelled, well-named dataset the search interface can interpret
- Best fit:
- Organisations where everyone waits on an analyst
- Connectivity:
- Connects to Snowflake, BigQuery, Redshift and Databricks over standard drivers, with REST APIs for automation
Public signals
Verified factual signals only. Bars appear only for like-for-like metrics with five weekly assessments for every tool; missing evidence stays explicit. These signals do not establish enterprise adoption, product quality, or total cost.
| Metric | Sigma Computing | ThoughtSpot |
|---|---|---|
| GitHub commits, 90d(Developer adoption) | 0 | 79 |
| GitHub stars(Developer adoption) | 6 | 13 |
| Search interest(Market interest) | 1 | 1 |
| Hacker News mentions, 90d(Community interest) | 0 | 0 |
| npm weekly downloads(Developer adoption) | 16.1k | 71.7k |
| Product Hunt comments(Community interest) | 1 | 3 |
| Product Hunt reviews(Community interest) | 0 | 0 |
| Product Hunt votes(Community interest) | 6 | 105 |
| PyPI weekly downloads(Developer adoption) | Not available | 127 |
As of September 21, 2026 — updated weekly.
Health & risk evidence
Observed public-source checks for mapped package versions and repositories.
Sigma Computing
September 21, 2026Package vulnerabilities
npm · @sigmacomputing/embed-sdk@0.7.1
0 vulnerabilities
across 1 package
Repository security score
Not available
ThoughtSpot
September 21, 2026Package vulnerabilities
npm · @thoughtspot/visual-embed-sdk@1.52.1 · PyPI · thoughtspot-rest-api-sdk@2.28.0
0 vulnerabilities
across 2 packages
Repository security score
github.com/thoughtspot/visual-embed-sdk
6.4/10
Interface Preview
Sigma Computing
ThoughtSpot
Feature Comparison
| Feature | Sigma Computing | ThoughtSpot |
|---|---|---|
| Interface | ||
| Spreadsheet-style grid and formulas | Full support | Not verified |
| Search-driven question answering | Not verified | Full support |
| Ad-hoc exploration by business users | Full support | Full support |
| Automated insight generation | Partial support | Full support |
| Governance | ||
| Live warehouse querying | Full support | Full support |
| No separate extract to refresh | Full support | Partial support |
| Governed metric definitions | Full support | Full support |
| Write-back to the warehouse | Full support | Partial support |
| Delivery | ||
| Dashboard authoring | Full support | Full support |
| Embedding in your own application | Full support | Full support |
| Alerting on data changes | Full support | Full support |
| Mobile access | Partial support | Full support |
| Platform | ||
| Warehouse connectivity | Full support | Full support |
| Scheduled distribution | Full support | Full support |
| Row-level security | Full support | Full support |
| REST API for automation | Full support | Full support |
Interface
Spreadsheet-style grid and formulas
Search-driven question answering
Ad-hoc exploration by business users
Automated insight generation
Governance
Live warehouse querying
No separate extract to refresh
Governed metric definitions
Write-back to the warehouse
Delivery
Dashboard authoring
Embedding in your own application
Alerting on data changes
Mobile access
Platform
Warehouse connectivity
Scheduled distribution
Row-level security
REST API for automation
Which to choose
Sigma and ThoughtSpot both try to remove an intermediary, and they remove different ones. Sigma removes the export: a spreadsheet grid over the warehouse where every action compiles to SQL, so people work the way they already do without copying data out. ThoughtSpot removes the ticket: a search box over a governed model so questions do not queue behind an analyst.
Best-fit scenarios
Choose Sigma Computing if:
Choose Sigma when everybody exports to a spreadsheet to do real work. A grid over the warehouse gives them the columns, formulas and pivots they actually use, with nothing copied out, nothing going stale, and governance staying where the data is.
Choose ThoughtSpot if:
Choose ThoughtSpot when people do not want a grid at all — they want an answer. If the cost in your organisation is managers waiting days for slices of existing data, a search interface over a governed model removes that wait in a way a better spreadsheet does not.
These scenarios reflect the available product evidence. Your requirements, existing stack, and team expertise should guide the final decision.
Frequently Asked Questions
Does a spreadsheet interface mean another copy of the data?
Not in this design — that is the point of it. Actions in the grid compile to SQL that runs against the warehouse, so there is no extract to refresh and nothing to go stale. The trade-off lands on warehouse compute instead: heavy interactive work is heavy querying, which on consumption pricing is a real line item. You are moving the cost, not removing it.
How far can people push a spreadsheet interface?
For pivoting, filtering, adding calculated columns and building on a result, far enough that most exports become unnecessary. For intricate multi-sheet financial models with circular references and bespoke layouts, not far enough, and those users will keep exporting. Look at what people actually do after they export today; that behaviour predicts whether this closes the gap for you.
What has to be true before search-first analytics works?
The model underneath has to be good. A search interface over well-modelled, well-named, governed tables is genuinely useful; the same interface over raw tables with cryptic column names produces confident answers to questions it has misunderstood, which is worse than no answer because nobody knows to check it. Modelling first, search second.
Where do metric definitions live in each?
Both are strongest when definitions live in the warehouse, and both make it easy not to. Sigma's grid lets an analyst define a calculation in a workbook, which is exactly the flexibility that makes people adopt it and exactly how two workbooks end up computing margin differently; its answer is datasets and reusable elements you curate centrally. ThoughtSpot centres worksheets and column metadata, because a search interface is only as good as the model it searches. The durable arrangement in both cases is dbt in the warehouse for anything reported, with tool-level definitions reserved for work that has not been standardised.
Does it query the warehouse, or a copy?
Both query live, which is unusual in this category and is the main thing they have in common. A Sigma workbook compiles its grid operations to SQL against Snowflake, BigQuery or Databricks, and a ThoughtSpot search does the same. Nothing is extracted, so there is one copy to govern, numbers reflect the warehouse now, and row-level security applied at the source applies everywhere. The consequence is that adoption shows up as warehouse compute rather than as a modelling and refresh burden. That is a real trade, not a free lunch.
How does licensing behave as the audience grows?
Sigma licenses people, with a lighter tier for those who only view, so the bill tracks headcount and is predictable once you have counted who builds and who reads. ThoughtSpot prices consumption, so the bill tracks use rather than seats, which suits a wide audience of occasional askers and moves when the organisation genuinely adopts it. Neither model is wrong; they fail differently. Per-seat pricing punishes wide rollouts with light use, and consumption pricing punishes success. Model your actual audience and its actual behaviour against both.
How should we evaluate them?
Build the same two things on both: the dashboard your executives read every Monday, and the open-ended question an analyst raised last quarter. The first tests modelling, refresh, delivery and governance; the second tests exploration. Most teams find one platform suited to each, which turns an abstract comparison into a decision about which half of the work matters more.