Buying snapshot
Scroll sideways to see all columns. With a keyboard, focus this table and use the arrow keys.
| Decision point | What CloudQuery states |
|---|---|
Deployment | Self-hosted: the database, the sync and the MCP server all run in your account. The guided deployment is one stack in your AWS account (the sync, a Postgres database and an MCP server). |
Air-gapped use | The license is validated locally, so it runs with no connection to CloudQuery endpoints. Telemetry can be turned off. |
License | MPL-2.0 license on the GitHub repository. |
Installation | CLI via |
How you query | Ask Claude, Cursor or any MCP-compatible agent in plain English, or query Postgres directly with SQL or a BI tool. |
Billing unit | Rows synced per year; subscriptions are billed annually. |
Our take
CloudQuery fits platform and security teams that need one SQL-queryable inventory across several cloud accounts and must keep that data in their own environment. If you want a hosted service that someone else runs, it is the wrong shape: every part of CloudQuery runs in your account.
Evaluate CloudQuery
Comparisons
Where it stands out
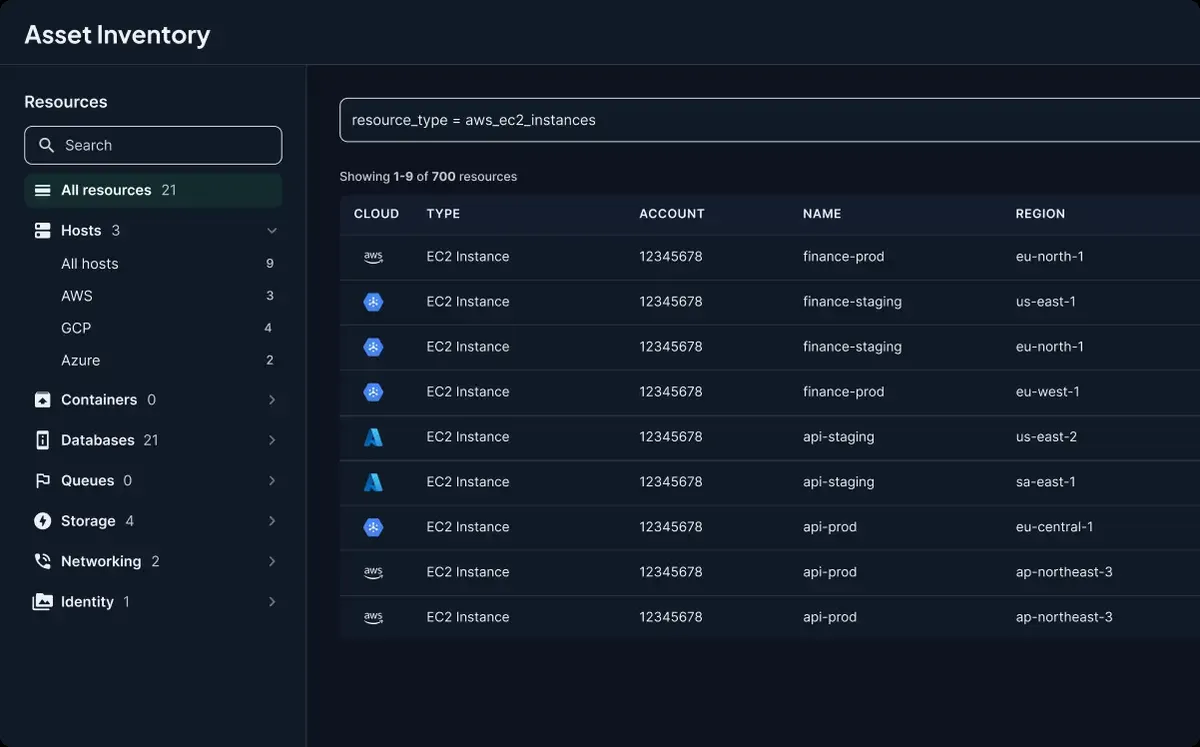
Data stays with you. CloudQuery says your inventory never leaves your account, so data kept in your environment by FedRAMP, GDPR or data-residency rules stays there.
Normalized data you can query with SQL. Plugins handle normalization and rate limits, so teams stop writing scripts against each cloud API.
Ownership, dependency and change questions. CloudQuery's demo answers show joins across sources: which resources a Wiz finding touches and who owns them (with Okta and PagerDuty), and what changed in an account in the last 24 hours from CloudTrail events.
Several jobs from one inventory. The project lists cloud asset inventory, cloud security posture management (CSPM) and FinOps, where it collects billing data from cloud providers.
Built for developers. Syncs are powered by Apache Arrow, and plugins are code-first and extensible, with a public plugin SDK.
Product screenshot

Trade-offs to weigh
Every sync counts. A row is counted each time a record is synced, whether it is new or updated. Sync frequency therefore drives row volume as much as estate size does.
The guided path starts in AWS. The homepage deployment is a stack in an AWS account that you point at your AWS Organization; Azure, GCP and Kubernetes are added afterwards as sources.
Not everything is open source. Only the framework, SDK, CLI and some integrations are open; some code that was open source moved to closed source. Check the license of each integration you depend on.
Source counts differ by page. The repository cites 70+ cloud and SaaS sources, while the Free plan lists 50+ cloud, security and FinOps sources. Confirm the sources you need are on your plan.
Round-the-clock support is Platinum only. The other paid support plans work business hours (9 AM - 5 PM Pacific Time).
Pricing and plan conditions
A row is any data record extracted from a source and loaded into your destination (for example Snowflake, BigQuery or Postgres). Beyond your committed baseline, additional usage is billed through a true-up at renewal or as an add-on during the year. Large or usage-based customers can discuss custom multi-year terms. A free trial environment is offered to test syncing before production, and discounts are offered for certain organizations.
Scroll sideways to see all columns. With a keyboard, focus this table and use the arrow keys.
| Plan | Published price | What it adds |
|---|---|---|
Free | $0, forever | 1M rows limitation; cloud asset inventory stored in your database; MCP server; 50+ cloud, security and FinOps sources; DIY dashboards and querying |
Enterprise | Custom (talk to sales) | Everything in Free, plus: 1M+ rows |
Scroll sideways to see all columns. With a keyboard, focus this table and use the arrow keys.
| Support plan | Initial response time (SLA) |
|---|---|
Free | Community support |
Silver | < 48 hrs (business hours) |
Gold | Business critical: 4 hours; degraded service: 12 hours; other issues: < 24 hrs (business hours) |
Platinum | Business critical: 1 hour; degraded service: 4 hours; other issues: 24 hrs (24×7) |
Technical Account Manager | Add-on at additional cost: dedicated guidance, implementation support and best practices |
Public signals
About these signals
Verified factual signals from public sources. They indicate observable activity or interest, not total adoption, product quality, or cost.
467 GitHub commits 90d6.6k GitHub starsOpenSSF score 5.3/10
See all signals from 3 sources
Alternatives to CloudQuery
The reviewed substitutes for CloudQuery among the ELT platforms, and what would make each one the better answer.
Other approaches
A different approach to the same problem. Each substitutes only for the workload named beside it.
- Airbyte
- Choose Airbyte if you need broad SaaS connector coverage with open-source flexibility and want a path from self-hosted to managed cloud.Applies to: For teams whose main sources are cloud infrastructure and security APIs rather than business apps.
- Fivetran
- Choose Fivetran if you want zero-maintenance data pipelines with the broadest connector library and enterprise-grade security clearances.Applies to: When the data to load comes from cloud provider APIs for infrastructure, security or FinOps work.
- Hevo Data
- Choose Hevo if your team lacks dedicated data engineers and you want a reliable, no-code platform with transparent pricing and strong customer support.Applies to: When cloud asset, security and cost data is what needs to reach the warehouse.
- Estuary Flow
- Choose Estuary if your workloads demand sub-minute data freshness and you need CDC streaming and batch processing in a single platform.Applies to: For teams that sync cloud infrastructure and compliance data on a schedule rather than streaming business events.
- Stitch
- Stitch and CloudQuery extract data from source systems and load it into cloud warehouses and databases. Stitch is a simple hosted ETL service, now owned by Qlik, for SaaS and database sources, while CloudQuery is an open-source framework centered on cloud infrastructure, security and compliance data.Applies to: When the sources are cloud accounts and security tools rather than SaaS business apps.
- dlt (data load tool)
- dlt (data load tool) and CloudQuery are open-source, code-first tools for extracting data from APIs and loading it into databases. dlt is a general Python library with schema inference, incremental loading and data contracts, while CloudQuery ships ready-made plugins aimed at cloud infrastructure, security and compliance data.Applies to: For teams that want ready-made plugins for cloud infrastructure and security data instead of writing Python pipelines.
- Kleene.ai
- CloudQuery and Kleene.ai each extract data from source systems and load it into a warehouse. CloudQuery is an open-source framework that engineers run, centered on cloud infrastructure, security and FinOps data, while Kleene.ai is a managed platform for business data that comes with delivery and advisory services.Applies to: When the data to load is cloud infrastructure and FinOps data and engineers will run the pipelines themselves.
- Meltano
- Meltano and CloudQuery are open-source, code-driven tools for extracting data and loading it into databases. Meltano is a general data movement tool built on Singer connectors with DevOps-style project files, while CloudQuery is tuned for pulling cloud infrastructure, security and FinOps data from cloud APIs.Applies to: When infrastructure, security and cost data from cloud APIs is the main thing to load.
- Sling
- Sling and CloudQuery are open-source, code-first tools for loading data into databases and warehouses. Sling focuses on copying data between files, databases and storage systems with quality checks, while CloudQuery focuses on extracting cloud API data for infrastructure, security and compliance work.Applies to: When the job is pulling cloud API data for infrastructure and security work rather than copying between databases and files.
- Portable
- Portable and CloudQuery both extract data from APIs and deliver it to warehouses or databases. Portable is a no-code hosted service built around connectors for business apps, while CloudQuery is an open-source framework for engineers that specializes in cloud infrastructure and security data.Applies to: When the sources are cloud provider APIs rather than long-tail business apps.
- Rivery
- As ELT tools, Rivery and CloudQuery both pull data from source systems into a warehouse. Rivery is a fully managed SaaS service with pre-built connectors for marketing, sales and operational data, while CloudQuery is open source and built for engineers who sync cloud infrastructure, security and FinOps data.Applies to: For engineering teams that need cloud infrastructure, security or FinOps data loaded into a warehouse.
Related technologies
Normally used together rather than chosen between, so these are not alternatives.
- Prefect
- An ELT tool lands data; an orchestrator decides what runs, in what order, and what happens when a step fails. The documented pattern runs both — Fivetran ships an Airflow provider, and code-first movement libraries are written to run inside an orchestrator — so the pair is a pipeline-and-scheduler pairing rather than a substitution. The question readers actually ask is whether both are needed.Applies to: Whether a managed or code-first ingestion tool removes the need for an orchestrator, or runs inside one.
Head to head
See detailed alternatives analysis
Looking for CloudQuery alternatives? CloudQuery is a powerful open-source ELT framework built in Go that specializes in extracting data from cloud APIs for infrastructure visibility, security posture management, and compliance. While CloudQuery excels at cloud asset inventory and SQL-based policy enforcement across AWS, GCP, Azure, and 50+ integrations, teams often need broader data pipeline capabilities, more SaaS connectors, or a fully managed experience. We evaluated the top CloudQuery alternatives across connector coverage, pricing, architecture, and operational overhead to help you find the right fit.
Top Alternatives Overview
Airbyte is the strongest open-source alternative with 600+ connectors and 21,000+ GitHub stars. It covers both SaaS and database replication with batch and CDC modes, and its Connector Development Kit lets you build custom connectors in under 30 minutes. Airbyte Cloud Standard starts at $20/month with 5 credits included, while the self-hosted edition is completely free. Choose Airbyte if you need broad SaaS connector coverage with open-source flexibility and want a path from self-hosted to managed cloud.
Fivetran is the market-leading managed ELT platform with 700+ fully managed connectors and proven enterprise scale, syncing 10.1 trillion rows per month across its customer base. It handles schema evolution, incremental updates, and connector maintenance automatically. The free tier includes 500,000 monthly active rows, with Enterprise plans offering 1-minute sync frequencies and hybrid deployment. Fivetran holds SOC 1/2, GDPR, HIPAA, ISO 27001, and PCI DSS Level 1 certifications. Choose Fivetran if you want zero-maintenance data pipelines with the broadest connector library and enterprise-grade security clearances.
Hevo Data is a no-code ELT platform with 150+ connectors and built-in dbt-based transformations. It processes over 1 petabyte of data monthly and offers log-based CDC for near-real-time database replication. Hevo pricing includes a Free plan limited to selected connectors and 1M events/month. Starter begins at $299/month billed monthly ($265/month billed annually) for 5M events/month; Professional begins at $849/month billed monthly ($750/month billed annually) for 20M events/month. Destination inserts, updates and deletes count as events; usage above quota incurs extra On-Demand charges. Hevo automatically handles schema drift and provides 24/7 engineer support. Choose Hevo if your team lacks dedicated data engineers and you want a reliable, no-code platform with transparent pricing and strong customer support.
Estuary Flow is a real-time ETL/ELT platform that supports sub-second CDC streaming alongside batch workloads. It starts at $50/month with tiers up to $1,000/month, using a usage-based model priced per GB. Estuary combines streaming-native transforms with dbt integration for analytics. Choose Estuary if your workloads demand sub-minute data freshness and you need CDC streaming and batch processing in a single platform.
Prefect is a Python-native workflow orchestration platform for data pipelines, ETL/ELT jobs, and ML workflows. It is fully open-source under the Apache 2.0 license with a managed cloud control plane available. Prefect focuses on workflow orchestration rather than data extraction, providing scheduling, retries, observability, and dependency management for arbitrary Python tasks. Choose Prefect if you need programmable orchestration for complex multi-step pipelines and your team writes Python-centric data workflows.
Stitch moves source data into cloud warehouses. Its US Standard pricing starts at $100/month for 5M rows/month, one destination and 10 Standard sources; contact Stitch for international pricing. A free trial is available, rather than a permanent free tier. Evaluate source coverage, row counting and destination limits before comparing its entry price with other services.
Architecture and Approach Comparison
CloudQuery is architecturally distinct from general-purpose ELT tools. It runs as a CLI written in Go that uses a plugin-based source/destination model to sync cloud infrastructure data into PostgreSQL, BigQuery, Snowflake, or other databases. Each sync extracts rows from cloud provider APIs (AWS, GCP, Azure, Kubernetes, and 70+ sources) and loads them into a normalized relational schema. The platform queries live infrastructure state rather than replicating application data, which makes it purpose-built for CSPM, FinOps, and cloud governance.
Airbyte and Fivetran take a connector-centric approach designed for SaaS and database replication. Airbyte runs each sync inside Docker containers with process isolation, using the Airbyte Protocol as a standardized JSON stream between source and destination. Fivetran operates as a fully managed service where connectors are maintained by the vendor, with automated schema evolution and idempotent pipelines that restart from the last successful state.
Hevo Data and Stitch sit on the managed, no-code end of the spectrum. Hevo uses isolated pipelines with auto-retries and self-healing schema mapping, while Stitch provides a lightweight extraction layer with minimal transformation. Estuary Flow stands apart with its streaming-first architecture that processes CDC events in sub-second latency, combining real-time and batch in one platform. Prefect operates at a different layer entirely as a workflow orchestrator: it schedules and monitors pipeline tasks but does not provide its own data connectors.
Pricing Comparison
Scroll sideways to see all columns. With a keyboard, focus this table and use the arrow keys.
| Tool | Free Tier | Starting Paid Price | Pricing Model | Enterprise |
|---|---|---|---|---|
| CloudQuery | CLI (open-source) | Rows synced/year | Usage-based (rows) | Contact sales |
| Airbyte | Self-hosted (unlimited) | $20/month (Cloud Standard) | Credits (volume-based) | Pro and Enterprise Flex quoted |
| Fivetran | 500K MAR | Usage-based MAR | Monthly Active Rows | Quoted (no published plan prices) |
| Hevo Data | 1M events | $299/month (Starter) | Event-based | Custom |
| Estuary Flow | Developer tier | $50/month | Per-GB usage | $1,000/month+ |
| Stitch | 1 user | $25/month (Pro) | Per-row | Enterprise custom |
| Prefect | Self-hosted (Apache 2.0) | Cloud plans available | Contact sales | Contact sales |
CloudQuery's open-source CLI is free with no row limits, but the managed Platform requires contacting sales for pricing based on annual rows synced. Hevo Data's $299/month Starter tier sits between Airbyte Cloud Standard's $20 entry and Fivetran's quoted plans, with the tradeoff being fewer connectors (150+) but built-in transformations and 24/7 support included.
When to Consider Switching
Switch from CloudQuery when your data needs extend beyond cloud infrastructure inventory. If you need to replicate data from SaaS applications like Salesforce, Stripe, HubSpot, or Google Analytics into a warehouse, tools like Airbyte (600+ connectors) or Fivetran (700+ connectors) cover those sources natively while CloudQuery does not.
Consider moving if you want a fully managed experience without operating CLI syncs. CloudQuery's self-hosted model requires running and scheduling syncs yourself, while Fivetran and Hevo Data handle everything from connector updates to schema evolution automatically. Teams that spent significant engineering time maintaining CloudQuery sync jobs report saving 40+ hours monthly after switching to managed platforms.
If real-time streaming matters to your use case, Estuary Flow delivers sub-second CDC latency that neither CloudQuery's batch sync nor most competitors can match. For teams that need workflow orchestration across multiple pipeline steps, ML training jobs, and custom Python logic, Prefect provides the scheduling and dependency management layer that CloudQuery lacks.
Stay with CloudQuery if your primary use case is cloud asset inventory, security posture management, or infrastructure compliance. No general-purpose ELT tool replicates CloudQuery's depth of coverage across AWS, GCP, Azure, Kubernetes, and security tools like Wiz in a single SQL-queryable schema.
Migration Considerations
CloudQuery uses a unique plugin-based architecture where sources and destinations are separate Go plugins. Migrating away means replacing CloudQuery's cloud API extraction with equivalent connectors in your target platform. Airbyte covers many cloud providers through its connector library, but the data schemas will differ from CloudQuery's normalized tables, so downstream SQL queries and dashboards need rewriting.
Data format compatibility is straightforward since CloudQuery loads into standard relational databases (PostgreSQL, BigQuery, Snowflake). Your existing destination tables and warehouse infrastructure remain usable with any replacement tool. The main migration effort centers on recreating extraction configurations and adapting any SQL-based policies or queries that reference CloudQuery's specific table schemas.
The learning curve varies significantly. Moving to Fivetran or Hevo Data reduces operational complexity since both are no-code platforms with web UIs. Switching to Airbyte keeps the open-source, self-hosted model but introduces Docker-based infrastructure and a different connector configuration system. Prefect requires Python proficiency and a fundamentally different mental model since you are writing orchestration code rather than configuring source-destination pairs.
For teams running CloudQuery alongside other tools, a gradual migration works well: keep CloudQuery for cloud infrastructure data where it excels, and add Airbyte or Fivetran for SaaS data replication. This hybrid approach avoids disrupting existing security and compliance workflows while expanding your data pipeline coverage.