Buying snapshot
Scroll sideways to see all columns. With a keyboard, focus this table and use the arrow keys.
| Decision point | What Acceldata states |
|---|---|
Deployment | xLake has one control plane and multiple compute planes for hybrid environments. Workloads and agents run where the data resides. The control plane is fully managed by the customer and hosts every Acceldata product. |
How it is sold | "Built as a Platform. Bought as Products." Every product runs on the xLake platform; use one or all of them. |
Getting a price | A pricing page with "pricing options for our products and solutions", a contact page, and an ROI calculator for value and cost savings from data observability. |
Processing engine (ADOC) | Spark, or the Pushdown engine, which runs compute inside the data source. Existing sources can switch from Spark to Pushdown. |
Pushdown sources | Snowflake, BigQuery, Databricks, SAP HANA, Azure Synapse, Oracle, Azure MSSQL, Amazon Redshift and MySQL. For Snowflake assets, Pushdown can also be chosen per data quality policy. Requires Data Reliability Observability enabled during integration. |
Hadoop platform | Open Data Platform: open-source Hadoop that runs on-prem, in the cloud, hybrid or on Kubernetes, with in-place, sidecar or forklift migration. |
Our take
Acceldata makes sense if your data spans on-premises, Hadoop and cloud systems and you want observability, Hadoop operations and agent-driven fixes under one control plane that you manage. If you run one cloud warehouse with a few quality checks, first confirm that the product you would buy covers your sources and rule types.
Evaluate Acceldata
Popular comparisons
See all 6 Acceldata comparisons
Where it stands out
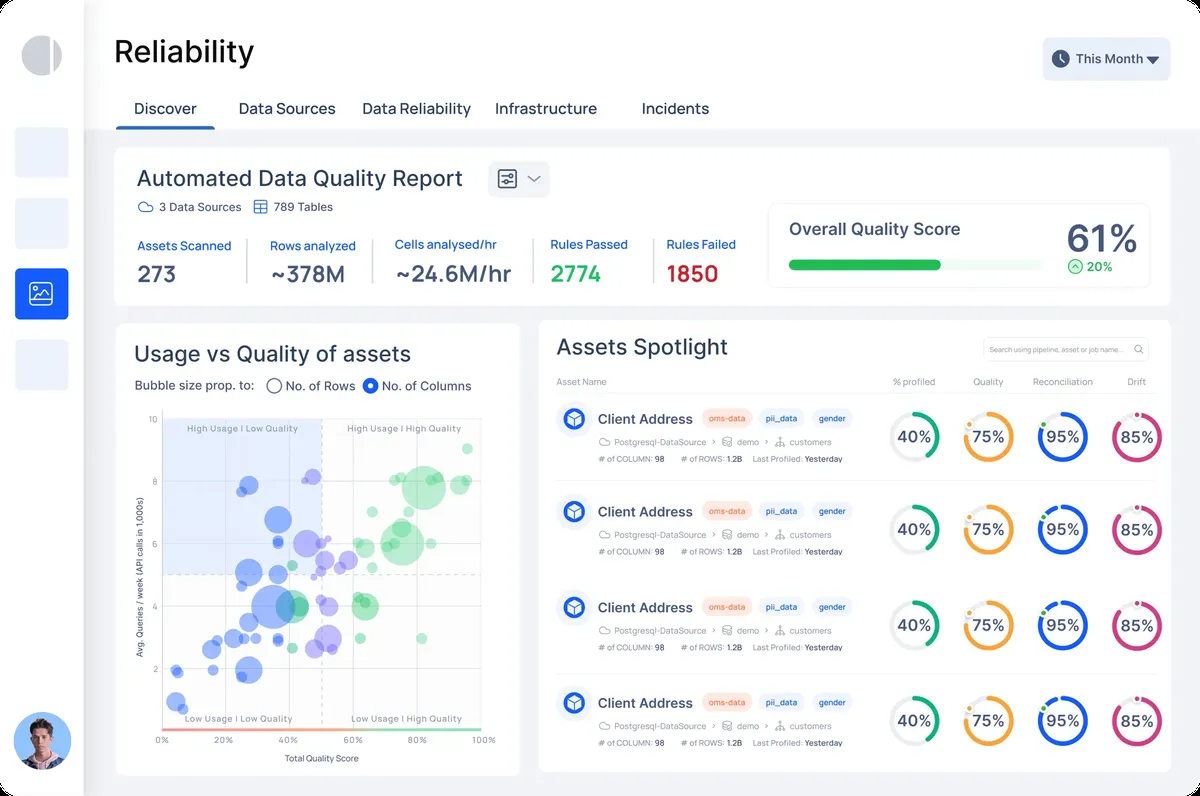
Broad data observability. The Data & AI Observability product covers data quality policies, reconciliation across systems, anomaly detection, profiling, alerts and lineage. xObserve watches cloud, hybrid and on-premise data, so one tool can cover a mixed estate.
Hadoop operations and migration. Hadoop Observability shows clusters, jobs, queues, users and cost in one place and includes Yarn optimization. The Open Data Platform adds Spark acceleration with Gluten and Velox. This suits teams still running Hadoop or moving off it.
From alert to fix. Acceldata describes an agent that walks the lineage to isolate the root cause, then applies a fix or proposes it for human approval. Every action is logged, and a confirmed incident becomes a permanent prevention rule.
Agents for data operations. Agentic Data Management offers agents for data quality, pipelines, the data catalog and incident management, with built-in agent validation.
AI observability in the same platform. Acceldata traces agents and LLMs across prompts, models, retrieval and tools, manages prompts and evaluations, and offers guardrails with PII controls, RBAC and audit trails.
A customer result. Acceldata quotes an SVP at a top national consumer bank: validating critical lending data went from "4+ hrs → 15 min". This is the vendor's example, not a benchmark.
Product screenshot

Trade-offs to weigh
Pushdown removes some rule types. With Pushdown, Data Policy Templates, SQ Rules, User Defined Rules and Lookups are not supported, Auto-Tag and Patterns do not work, and record persistence is disabled. If you rely on those rules, check them before switching a source to Pushdown.
You buy products, not one tool. Because each product is sold separately on one platform, decide which products and data sources the purchase covers before comparing Acceldata with a single-purpose data quality tool.
You run the control plane. Customer control over where Acceldata runs also means your team owns operating it.
Automatic fixes need rules. Since fixes can be applied or only proposed for approval, decide which changes may run without a person signing off.
Public signals
About these signals
Verified factual signals from public sources. They indicate observable activity or interest, not total adoption, product quality, or cost.
2.8k PyPI weekly downloadsTop 93% Google Trends search interest0 vulnerabilities across 1 package
See all signals from 3 sources
PyPI · acceldata-sdk@26.10.0
Alternatives to Acceldata
The reviewed substitutes for Acceldata among the data observability, and what would make each one the better answer.
Direct alternatives
Reviewed substitutes: products bought for the same job, where a team picks one.
- Anomalo
- Acceldata and Anomalo watch enterprise data for quality problems and alert teams before bad data spreads. Anomalo puts its weight on AI that detects and root-causes issues across structured, semi-structured and unstructured data, while Acceldata adds pipeline monitoring and governance to observability in one data management platform.Applies to: Choosing between these two for the data observability decision.
- Bigeye
- Bigeye and Acceldata are enterprise platforms that monitor data quality, detect anomalies and trace problems to their cause. Bigeye stresses end-to-end lineage and governance of data used by AI, while Acceldata extends into pipeline monitoring and AI agents that automate data management.Applies to: Choosing between these two for the data observability decision.
- Metaplane
- Metaplane and Acceldata alert data teams when something breaks in their data and help them find what went wrong. Metaplane concentrates on continuous monitoring with debugging metadata in every alert, while Acceldata is an enterprise platform that adds pipeline monitoring, governance and AI agents.Applies to: Choosing between these two for the data observability decision.
- Monte Carlo
- Monte Carlo and Acceldata are enterprise platforms that monitor data across pipelines and warehouses and raise incidents when something breaks. Monte Carlo is centred on ML-driven anomaly detection and incident triage, while Acceldata also covers pipeline performance and governance and uses AI agents to keep data reliable.Applies to: Choosing the data observability platform that will monitor the warehouse and own incidents.
- DataBuck
- Reviewed same-category buyer alternative: DataBuck is a context-aware enterprise data-quality platform for validation discovery, reconciliation, remediation, and anomaly detection.
Other approaches
A different approach to the same problem. Each substitutes only for the workload named beside it.
- Atlan
- A catalog organises assets for discovery and governance; an observability platform detects incidents and monitors reliability. Lineage and metadata overlap enough that vendors on both sides publish guidance on whether one covers the other, and teams with a trust problem rather than a discovery problem do buy the observability platform instead of a catalog. The decision is which capability the organisation needs first, and whether one product covers both.Applies to: Whether discovery and reliability need two products, or one platform can carry both.
- Soda
- Soda and Acceldata both find data quality issues and help teams resolve them. Soda centers on checks that run in the pipeline, from table to record level, with AI to automate them, while Acceldata monitors data, pipelines and governance across the enterprise with AI agents. Teams that enforce quality at pipeline steps lean to Soda, and those wanting estate-wide monitoring lean to Acceldata.Applies to: Deciding how data quality is enforced: automatic monitoring or checks written in the pipeline.
- Great Expectations
- Great Expectations and Acceldata both keep bad data from reaching reports and models. Great Expectations is an open-source framework in which engineers write expectations and run them inside the pipeline, while Acceldata is an enterprise platform that monitors data and pipelines automatically with AI agents. The choice turns on hand-written checks versus automatic monitoring.Applies to: Deciding how data quality is enforced: automatic monitoring or checks written in the pipeline.