Buying snapshot
Scroll sideways to see all columns. With a keyboard, focus this table and use the arrow keys.
| Decision point | What Exasol states |
|---|---|
Deployment | AWS, Azure, GCP, Kubernetes or on-prem; any public, sovereign or private cloud |
Licensing basis | RAM-based licensing, as described in Exasol's MEDION customer story |
Stack fit | Works with Tableau, Power BI, dbt, Python and Spark; also named for Looker dashboards |
Python driver | PyExasol, the officially supported connector, MIT license; needs Exasol >= 7.1 and Python >= 3.11 |
Our take
Exasol fits teams that want a fast SQL analytics engine they can run on their own infrastructure or the cloud of their choice, and that want to keep BI tools and in-database models on the same data. If you are weighing it, test your own queries on the free Personal edition before you rely on the vendor's speed figures.
Evaluate Exasol
Popular comparisons
Where it stands out
Control over data and governance. Exasol says buyers control where data runs and how governance is enforced. This matters for teams with data residency rules.
Little tuning work. Exasol describes a self-tuning engine that automates indexing and removes manual tuning. Teams without a dedicated DBA carry less upkeep.
Models run next to the data. You can train and run Python, R and Java models directly in Exasol, so data does not move to a separate ML system. Exasol also names TensorFlow, PyTorch, Spark ML and cloud AI services as connections.
Agent access built in. Exasol offers native MCP support, an MCP Server and reusable Agent Skills, so AI agents can query the database without a custom integration layer.
Acceleration without a migration. Exasol can sit between your data sources and BI tools to speed up dashboards, and it says it accelerates lakehouse workloads without code changes or replatforming. This lets a team test it as a layer before replacing a warehouse.
Parallel Python loading. PyExasol can read and write several data streams in parallel using separate processes, with HTTP transport for pandas, parquet and polars and compression to reduce network load.
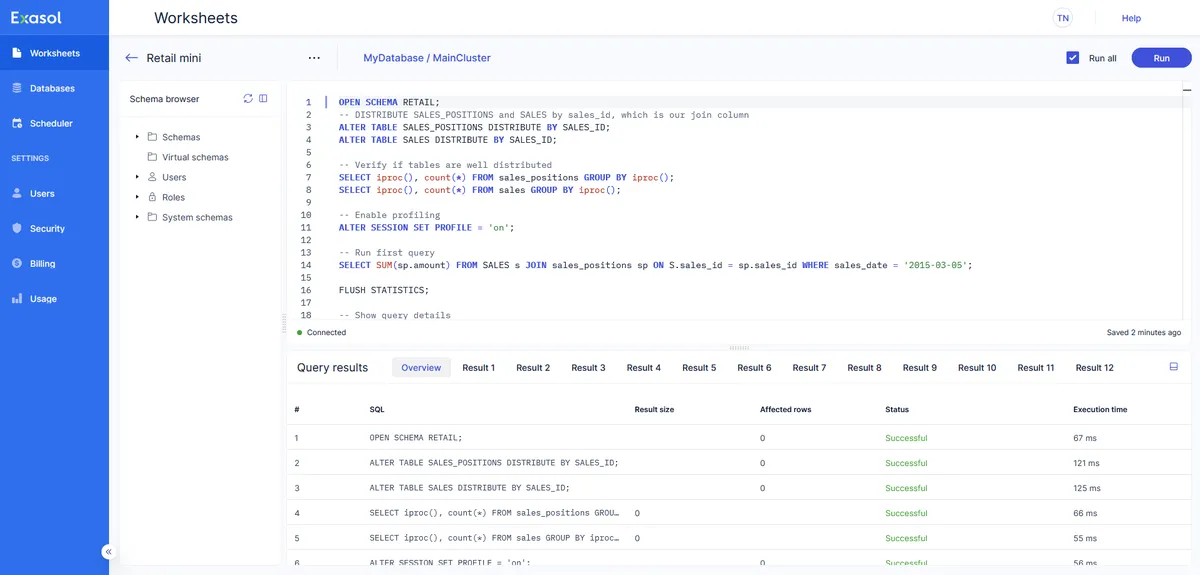
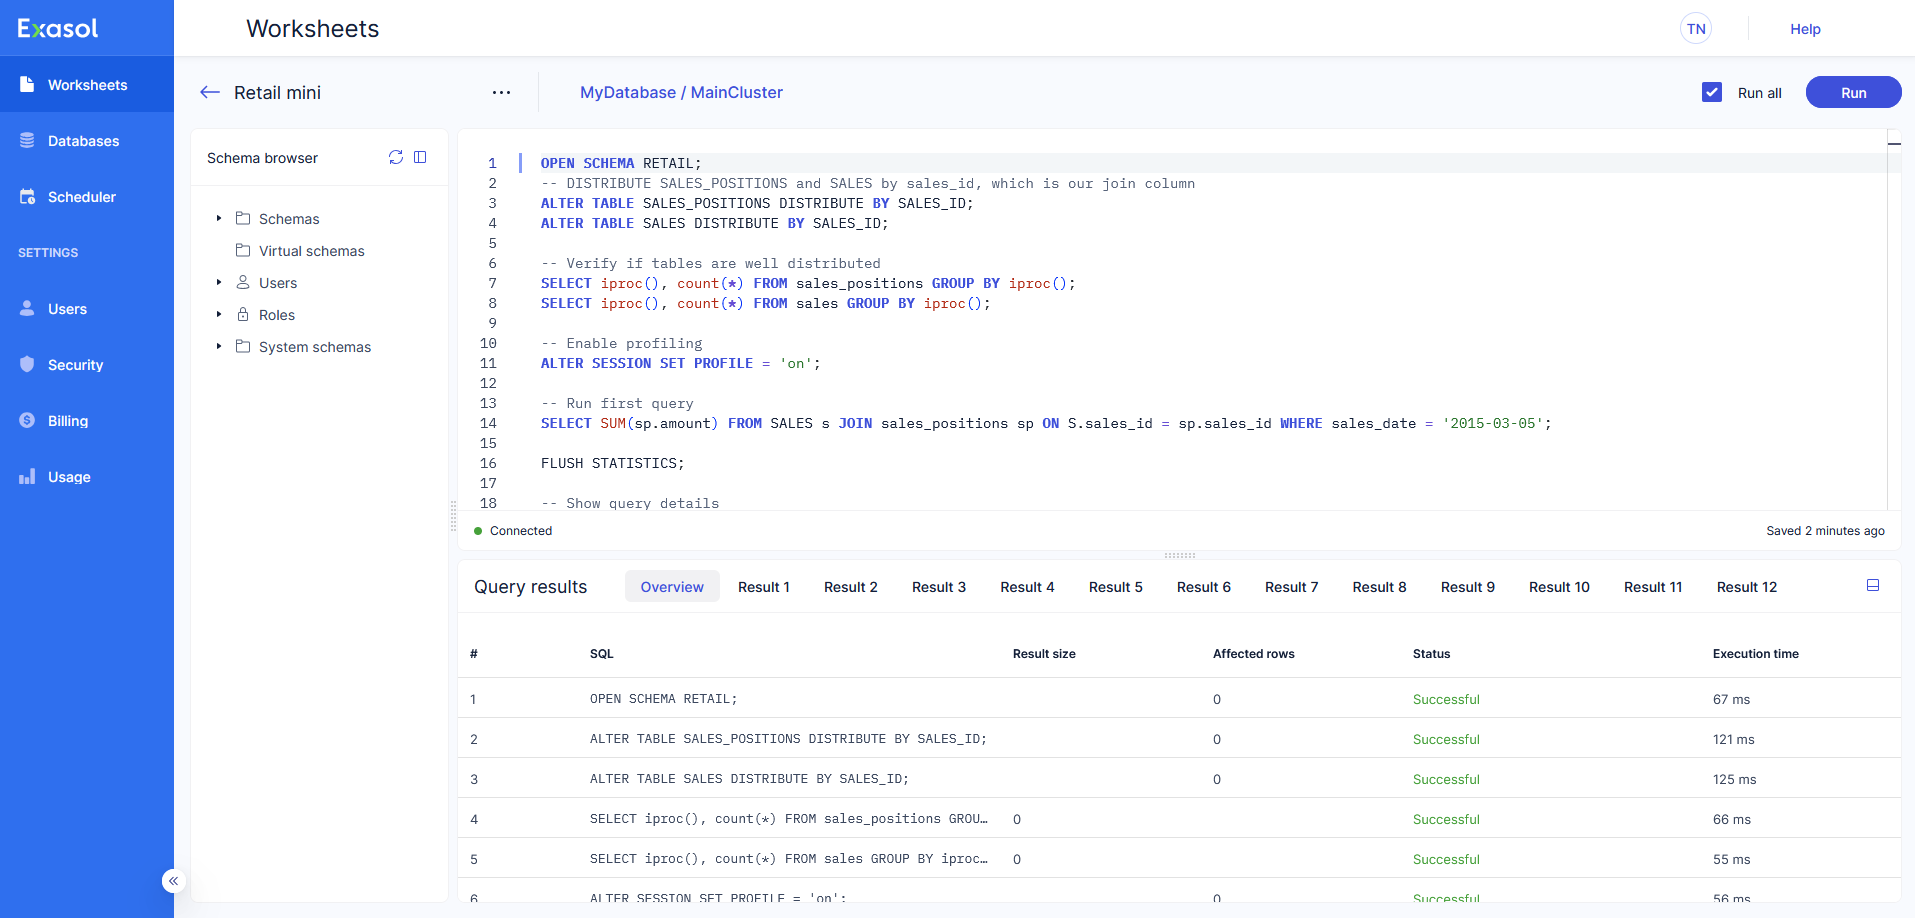
Product screenshot
Trade-offs to weigh
Speed and cost figures come from the vendor. Exasol claims 10x to 1000x faster queries with in-memory computing and up to 65% lower TCO. Customer stories report results such as 1,400% faster data loads at Digital Planet and 164x faster reporting at Spread Group. Treat these as vendor-reported and check them against your own workload.
Older clusters limit the Python driver. Teams on Exasol or Python versions below the PyExasol minimums may need an upgrade before they can use the current driver.
Pricing and plan conditions
Evaluation can run on Personal at no charge. Production use belongs to Enterprise, so ask Exasol how the Enterprise licence is measured for your deployment before you move proven workloads over.
Scroll sideways to see all columns. With a keyboard, focus this table and use the arrow keys.
| Edition | What Exasol states |
|---|---|
Exasol Personal | Free. Build, test and validate analytics, AI and agentic use cases; flexible deployment options; connect enterprise data and query in place |
Exasol Enterprise | Production analytics and AI workloads with governance, control and support; share data products across the enterprise; scale with predictable costs |
Public signals
About these signals
Verified factual signals from public sources. They indicate observable activity or interest, not total adoption, product quality, or cost.
45 GitHub commits 90d83 GitHub stars0 vulnerabilities across 2 packages
See all signals from 8 sources
npm · @exasol/exasol-driver-ts@0.8.1 · PyPI · pyexasol@4.1.0
Alternatives to Exasol
The reviewed substitutes for Exasol among the cloud data warehouses, and what would make each one the better answer.
Direct alternatives
Reviewed substitutes: products bought for the same job, where a team picks one.
- Azure Synapse Analytics
- Azure Synapse Analytics and Exasol both run a company's central SQL data warehouse for reporting and analytics. Synapse is Microsoft's managed service on Azure and adds Spark and data integration in the same workspace. Exasol is a commercial in-memory, columnar engine that a team can run on its own servers or in the cloud, with a focus on raw query speed.Applies to: Choosing between these two for the cloud data warehouses decision.
- Vertica
- Vertica and Exasol are commercial columnar databases for fast analytical SQL on large data. Exasol emphasises in-memory processing for query speed. Vertica emphasises advanced compression and in-database machine learning, and also covers lakehouse workloads.Applies to: Choosing between these two for the cloud data warehouses decision.
- Teradata
- Teradata and Exasol both sell high-performance analytical databases for enterprise warehousing, in the cloud or on-premises. Teradata stresses a broad platform for very large and mixed workloads across hybrid and multi-cloud setups. Exasol stresses in-memory, columnar speed for analytics teams that want quick answers.Applies to: Choosing between these two for the cloud data warehouses decision.
- Firebolt
- Analytics teams that need very fast SQL on large data can run it on Firebolt or on Exasol. Firebolt is a managed cloud warehouse built for high concurrency and fast ingestion behind customer-facing analytics. Exasol is a commercial in-memory MPP database that can also run on-premises, which appeals to teams that keep data in their own data center.Applies to: Choosing between these two for the cloud data warehouses decision.
- Yellowbrick Data
- For a fast enterprise warehouse that stays under a team's own control, Exasol and Yellowbrick Data are both candidates. Exasol puts the emphasis on in-memory, massively parallel query speed for analytics. Yellowbrick is built on Kubernetes and stresses deployment in private clouds and data centers for data residency and sovereignty.Applies to: Choosing between two products of the same kind for one job.
Other approaches
A different approach to the same problem. Each substitutes only for the workload named beside it.
- Snowflake
- Both answer the same enterprise analytics question with a columnar MPP engine. The difference in kind is architecture and hosting: Exasol is an in-memory analytics database run self-hosted or in your own cloud account, tuned for query latency, while snowflake is a managed, storage-separated service that scales compute on demand.Applies to: Enterprise SQL analytics on a central warehouse: BI dashboards, ad-hoc exploration and scheduled transformation over the same governed dataset. Choose Exasol when query latency on a bounded working set matters most and you will operate the database; choose snowflake for elastic managed capacity.
- Google BigQuery
- Both answer the same enterprise analytics question with a columnar MPP engine. The difference in kind is architecture and hosting: Exasol is an in-memory analytics database run self-hosted or in your own cloud account, tuned for query latency, while google-bigquery is a managed, storage-separated service that scales compute on demand.Applies to: Enterprise SQL analytics on a central warehouse: BI dashboards, ad-hoc exploration and scheduled transformation over the same governed dataset. Choose Exasol when query latency on a bounded working set matters most and you will operate the database; choose google-bigquery for elastic managed capacity.
- Databricks
- When a team picks its central SQL warehouse, Databricks and Exasol can both take that role. Exasol is a dedicated in-memory analytics database focused on query speed, on-premises or in the cloud. Databricks runs SQL warehousing on a lakehouse that also covers data engineering and machine learning, which counts if the warehouse decision includes those teams.Applies to: Choosing between these two for the cloud data warehouses decision.
- Amazon Redshift
- Both answer the same enterprise analytics question with a columnar MPP engine. The difference in kind is architecture and hosting: Exasol is an in-memory analytics database run self-hosted or in your own cloud account, tuned for query latency, while redshift is a managed, storage-separated service that scales compute on demand.
- ClickHouse
- Two analytical databases that reach low latency differently: Exasol holds working data in memory with self-tuning indexes and is bought as capacity, ClickHouse is columnar with explicit index and engine choices and is commonly self-hosted. The generated 'complementary' proposal is wrong; these are alternatives for one workload.Applies to: Choosing an analytical database for concurrent interactive queries.
- MotherDuck
- Teams that want fast SQL analytics without heavy tuning work can choose MotherDuck or Exasol. Exasol is an in-memory MPP database sold for enterprise workloads and runs on-premises or in the cloud. MotherDuck is a serverless cloud service built on DuckDB, aimed at lean teams that do not want to manage any infrastructure.Applies to: For teams that want fast SQL analytics at small or mid-size data volumes without running an in-memory cluster.