Buying snapshot
Scroll sideways to see all columns. With a keyboard, focus this table and use the arrow keys.
| Decision point | What the Marquez project states |
|---|---|
License | Open source under the Apache-2.0 license |
Installation | Self-hosted. The easiest way to start is with Docker (./docker/up.sh, with an optional --seed flag for sample lineage metadata); the repository also has a Helm chart module and build-from-source steps |
Requirements to build from source | Java 17 and PostgreSQL 14; a marquez.yml file sets the database connection |
Data scope | Dataset, job and run metadata collected using OpenLineage |
Interfaces | Web UI, HTTP API with an admin interface (/healthcheck and /metrics), and a GraphQL endpoint that is currently in beta |
Project governance | LF AI & Data Foundation Graduated project under active development |
Community and security reports | MarquezProject Slack chat; vulnerabilities are reported by opening a GitHub issue with the "security" label |
Our take
If your pipelines already run on tools with OpenLineage integrations and your team can operate its own service and database, Marquez is a direct way to turn those events into a lineage graph you control. If you want a product someone else runs for you, Marquez is the wrong fit, because the project ships it as software you deploy yourself.
Evaluate Marquez
Popular comparisons
See all 5 Marquez comparisons
Where it stands out
Works with existing OpenLineage integrations. As the reference implementation, the Marquez API server already works with the integrations built by the OpenLineage community, including Apache Airflow, Apache Spark, Apache Flink, dbt and Dagster. Teams on those tools configure an integration rather than write a connector.
Real-time collection from running jobs. The metadata server offers an OpenLineage-compatible endpoint that collects information from running jobs and applications as they run, so the graph reflects what executed.
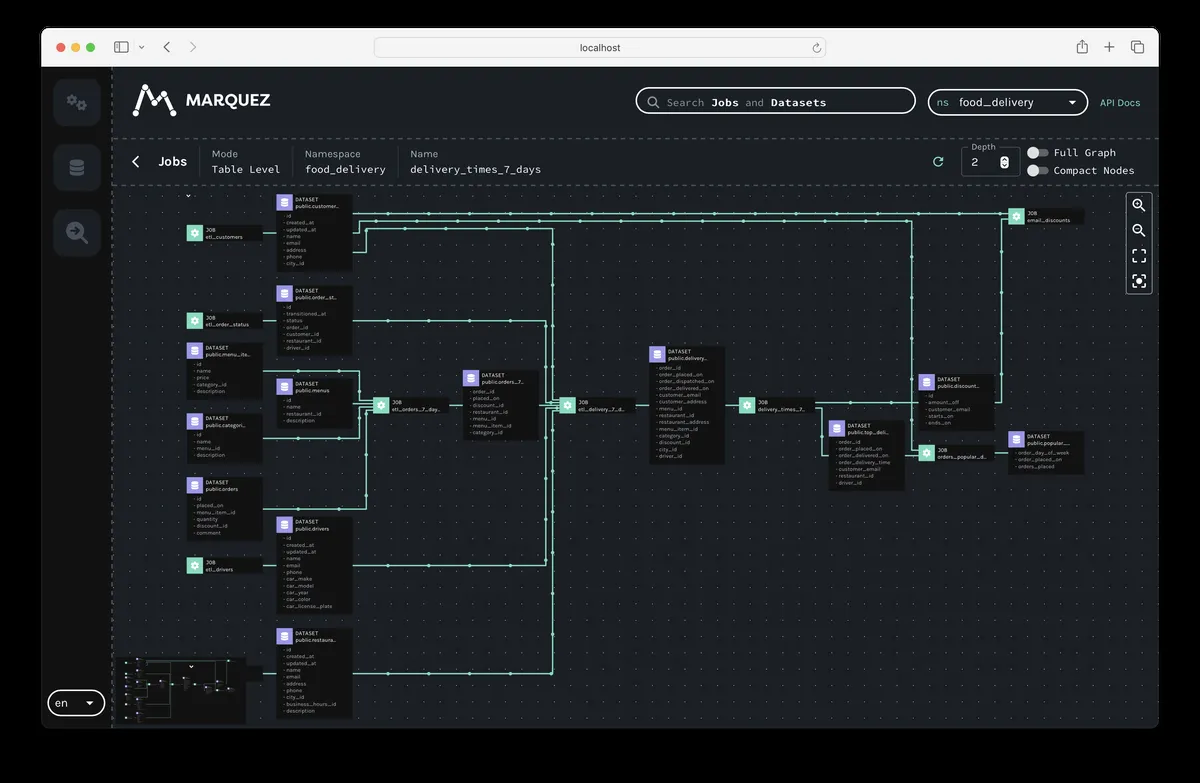
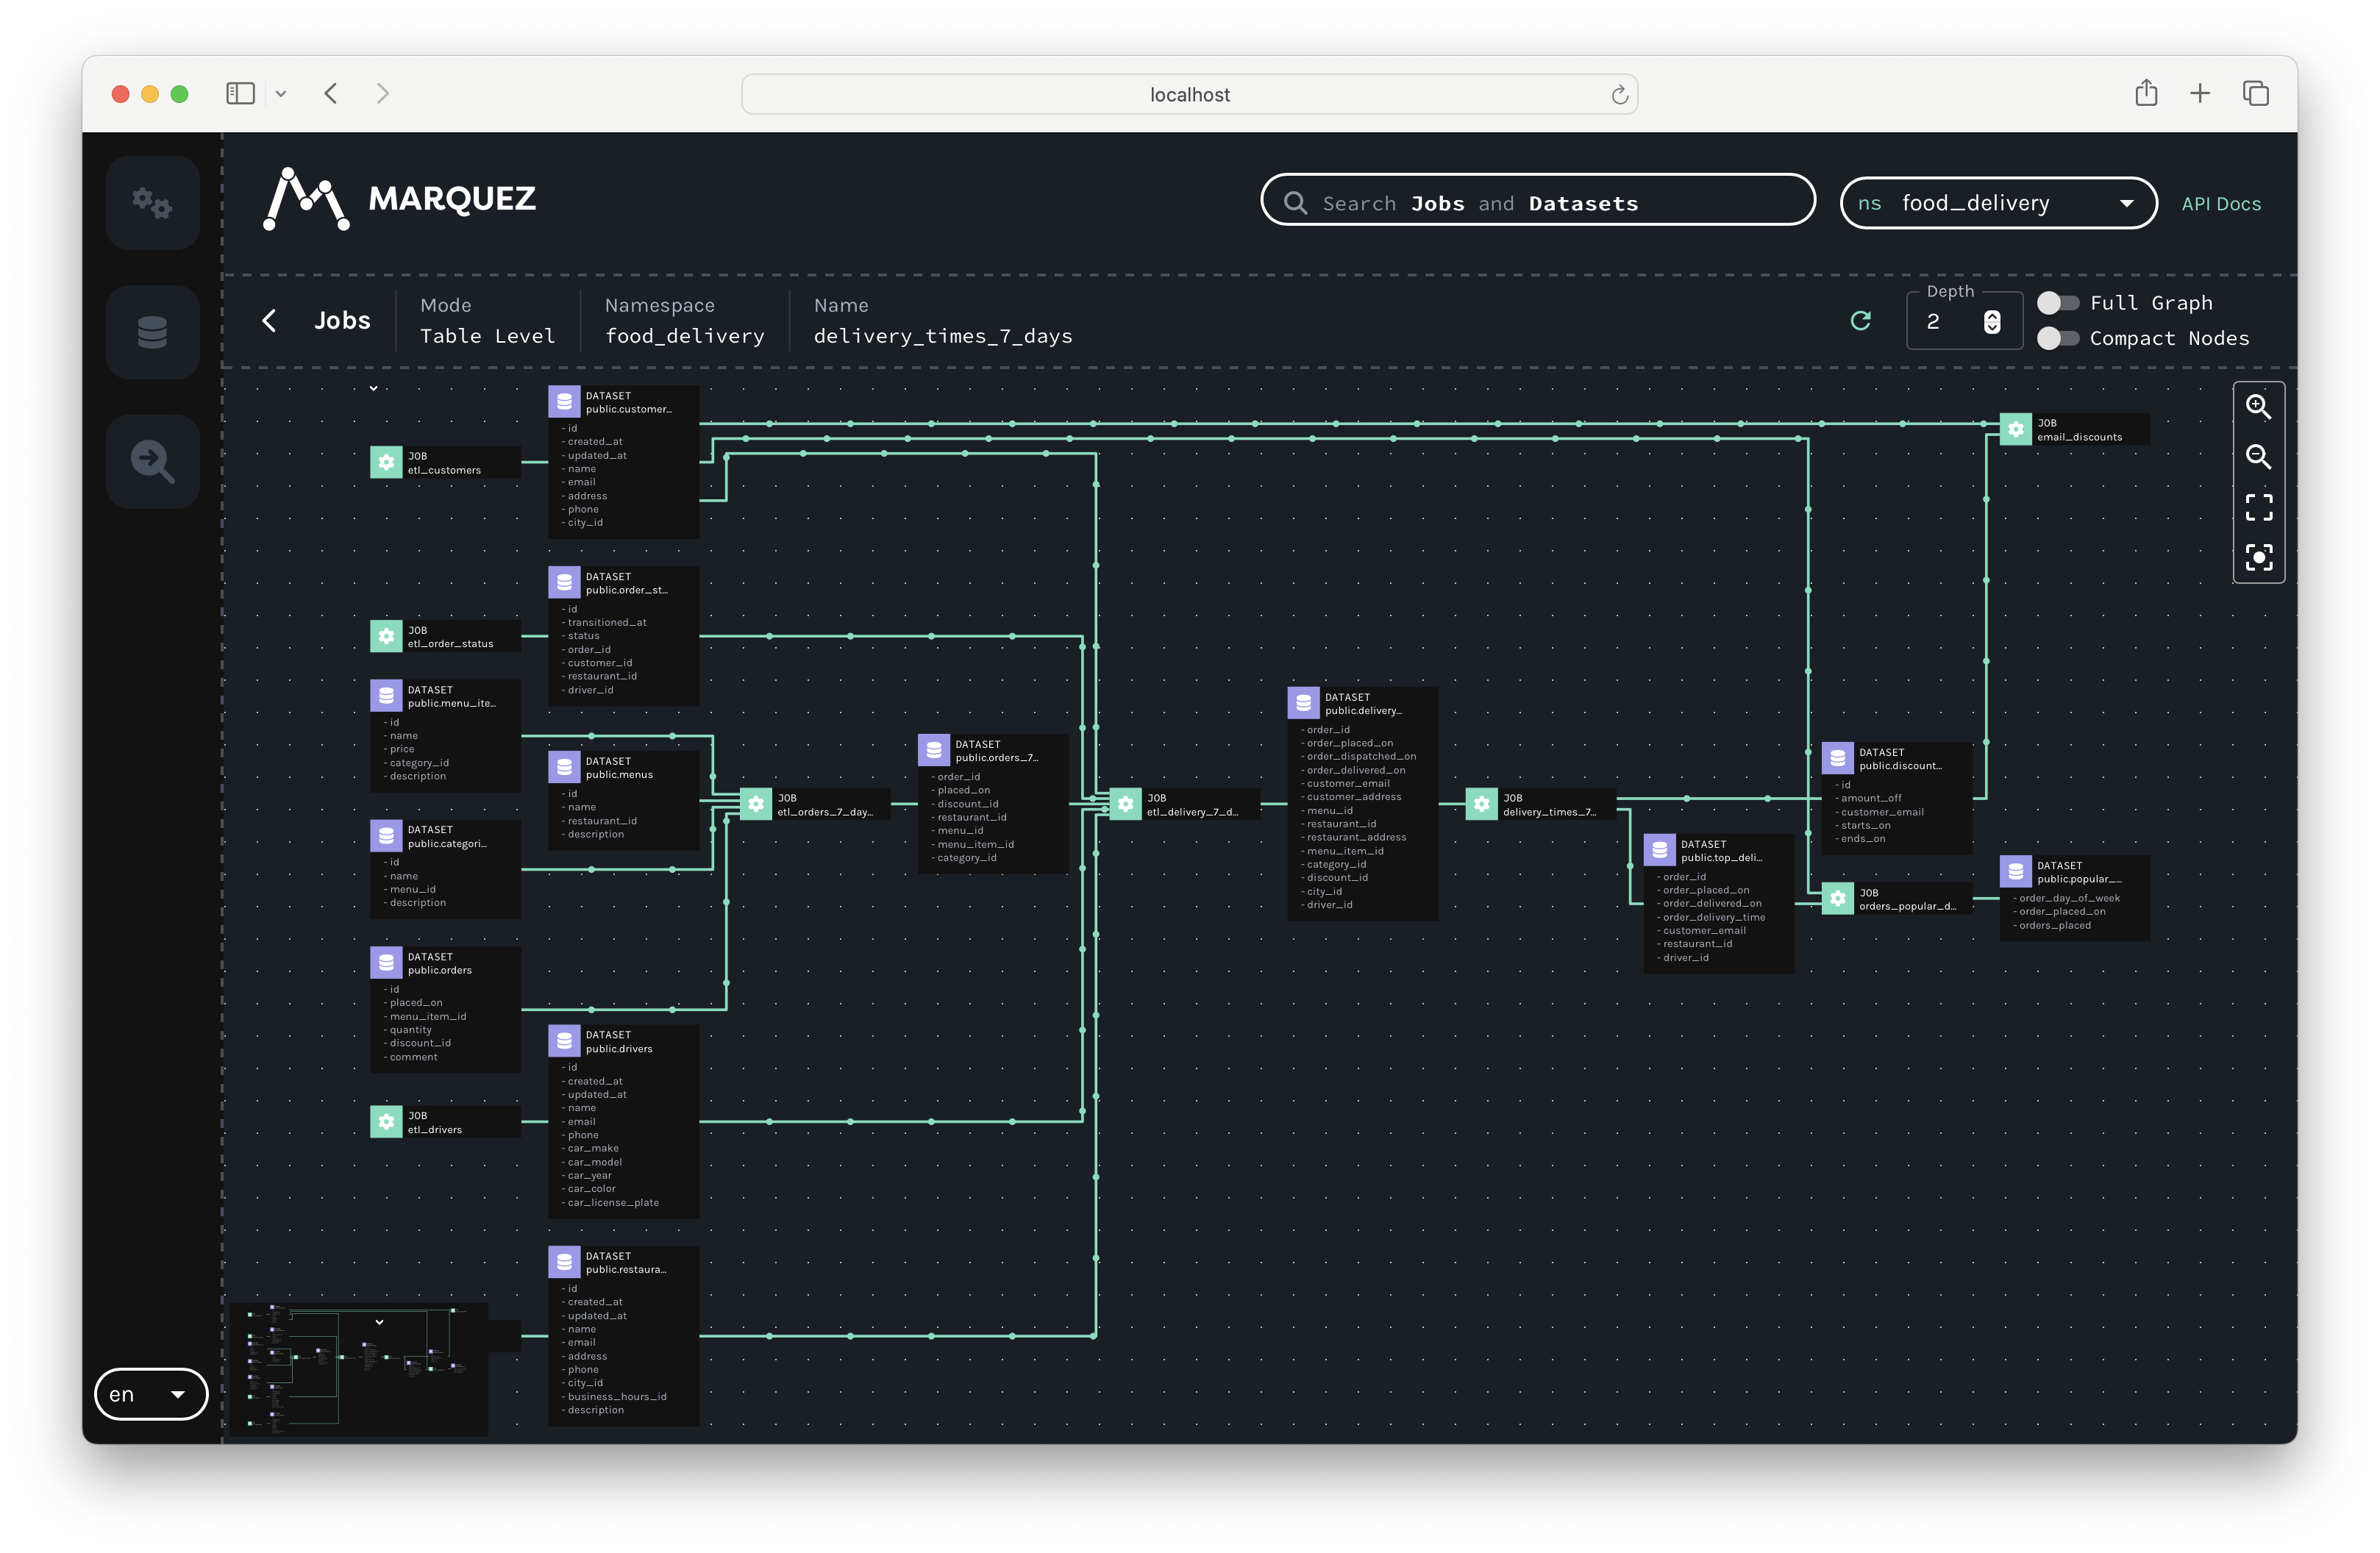
Run-level detail for incident work. The web UI shows the inputs and outputs of each job, traces the lineage of individual datasets, and shows performance metrics and execution details, including run metadata for current and previous job runs.
A Lineage API for automation. You can query metadata to automate tasks such as backfills and root cause analysis, traverse the dependency tree across pipelines and orchestration platforms, and use it to enrich data catalogs and data quality systems.
Named adopters. The repository's Adopters list names Astronomer, Datakin, Northwestern Mutual, Ilum and CsvPath.
Product screenshot
Trade-offs to weigh
No authentication by default. The project states that, by default, the HTTP API does not require any form of authentication or authorization. Plan network access controls before you expose it beyond a trusted network.
Lineage comes from events you send. You collect lineage metadata as OpenLineage events through the LineageAPI or an OpenLineage integration; the Marquez integrations module was removed in 0.21.0. Graph coverage therefore depends on which jobs you instrument.
Pick a released version for production. Marquez 0.50.0 is marked RECOMMENDED (OpenLineage 2-0-2) and 0.49.0 is in MAINTENANCE, which gets bug fixes whenever possible. The unreleased CURRENT version does not come with any guarantees.
Extra setup on Windows. Before cloning, Windows users configure Git for Unix-style line endings (core.autocrlf false) and make sure Bash and PostgreSQL are on the PATH.
Public signals
About these signals
Verified factual signals from public sources. They indicate observable activity or interest, not total adoption, product quality, or cost.
0 GitHub commits 90d2.3k GitHub stars0 vulnerabilities across 1 packageOpenSSF score 4.0/10
See all signals from 5 sources
PyPI · marquez-python@0.50.0
Alternatives to Marquez
The reviewed substitutes for Marquez among the data catalogs, and what would make each one the better answer.
Other approaches
A different approach to the same problem. Each substitutes only for the workload named beside it.
- Elementary
- Choose Elementary if your stack is built around dbt and you want lineage plus quality monitoring tightly integrated with your transformation layer.Applies to: Whether discovery and reliability need two products, or one platform can carry both.
- Atlan
- Atlan and Marquez both collect data lineage and show how datasets and jobs connect across pipelines. Marquez is the open-source reference server for OpenLineage and covers lineage and metadata collection, while Atlan is a commercial catalog that adds search, a business glossary and governance workflows on top.Applies to: For teams that need lineage tracking only, without a business glossary or governance workflows.
Related technologies
Normally used together rather than chosen between, so these are not alternatives.
- Great Expectations
- A validation framework defines and runs checks; a catalog stores and displays the results beside lineage, ownership and glossary. Catalogs integrate the check tools rather than replacing them, so the pair is deployed together and the reader's question is which job each one does.Applies to: Whether a data catalog removes the need for a separate checks tool, or reports what it found.
- Soda
- A validation framework defines and runs checks; a catalog stores and displays the results beside lineage, ownership and glossary. Catalogs integrate the check tools rather than replacing them, so the pair is deployed together and the reader's question is which job each one does.Applies to: Whether a data catalog removes the need for a separate checks tool, or reports what it found.
- Monte Carlo
- Monte Carlo detects data incidents with ML-driven anomaly detection; Marquez is an open-standard lineage collection service. Lineage is an input to incident triage, not a replacement for detecting the incident.Applies to: Marquez supplies the lineage Monte Carlo uses to trace an incident to its source.
Head to head
See detailed alternatives analysis
Marquez is an open-source metadata service built specifically for collecting, aggregating, and visualizing data lineage. As the reference implementation of OpenLineage, it provides a standardized way to track data dependencies across pipelines. If you are evaluating Marquez alternatives, the right choice depends on whether you need a pure lineage tool, a broader metadata catalog, or a full data observability platform.
Top Alternatives Overview
DataHub is the leading open-source metadata platform, offering data discovery, observability, and federated governance under an Apache 2.0 license. Unlike Marquez's narrow focus on lineage, DataHub provides a full data catalog with search, tagging, ownership tracking, and automated metadata ingestion from dozens of sources. It also offers a managed cloud version with enterprise features like saved searches and email alerts. Choose DataHub if you need a comprehensive metadata platform that goes well beyond lineage tracking.
OpenMetadata is a unified metadata platform with 14,000+ GitHub stars and 120+ native connectors covering databases, dashboards, pipelines, and ML models. Built by the founders of Apache Hadoop, Apache Atlas, and Uber Databook, it combines data discovery, quality, observability, and governance in a single platform with a schema-first API architecture. It reports over 3,000 enterprise deployments and 370+ code contributors. Choose OpenMetadata if you want an all-in-one open-source platform that replaces multiple point solutions including lineage, cataloging, and data quality.
Great Expectations is the open-source standard for data quality testing with 11,000+ GitHub stars, a Python-based framework, and a newer GX Cloud managed service. It focuses on codified data expectations rather than lineage, letting teams write explicit validation rules that double as living documentation. The framework integrates with CI/CD pipelines, orchestration tools, and can auto-generate tests using its ExpectAI feature. Choose Great Expectations if your primary concern is validating data correctness rather than tracking lineage across pipelines.
Elementary is a dbt-native data observability platform with column-level lineage, automated anomaly detection, and incident management. Its cloud plans start at a Scale tier with up to 10 editor seats and 5,000 tables, with Enterprise and Unlimited tiers adding SSO, RBAC, and dedicated support. Elementary manages all configurations in dbt code, enabling version control and code review for observability settings. Choose Elementary if your stack is built around dbt and you want lineage plus quality monitoring tightly integrated with your transformation layer.
Collibra is an enterprise-grade data governance platform headquartered in Brussels, offering unified governance for data and AI. It provides data cataloging, policy management, compliance automation, and lineage tracking through a cloud-based platform trusted by regulated organizations. Pricing requires contacting sales, reflecting its enterprise positioning. Choose Collibra if you are a large regulated enterprise that needs compliance-driven governance, audit trails, and business glossary management alongside lineage.
Castor (CastorDoc) is an automated data discovery and catalog tool that provides Google-like search for finding tables and datasets across your organization. It focuses on making data assets discoverable and well-documented, with automated metadata enrichment and contextual documentation. Choose Castor if your biggest pain point is data discovery and you want a user-friendly catalog that non-technical stakeholders can actually navigate.
Architecture and Approach Comparison
Marquez takes a deliberately narrow architectural approach: it is a real-time metadata server with an OpenLineage-compatible API endpoint that collects lineage events from running jobs. Written in Java, it stores lineage metadata in PostgreSQL and exposes it through a REST API and web UI. This simplicity is its strength for teams that only need lineage, but it means you must bolt on separate tools for data quality, cataloging, and governance.
DataHub and OpenMetadata take the opposite approach with extensible metadata graphs that model relationships between datasets, pipelines, dashboards, users, and policies. OpenMetadata uses a four-component architecture designed for simple deployment and operates with a TypeScript frontend and Java backend. DataHub uses a graph-based metadata store (built on Apache Kafka and Elasticsearch) that supports real-time metadata changes and programmatic access through its GraphQL API.
Great Expectations and Elementary focus on the data quality layer rather than metadata management. Great Expectations runs validation checkpoints directly inside your Python pipelines, while Elementary operates as a dbt package that executes within your data warehouse. Neither replaces Marquez's lineage capabilities directly, but both provide the quality monitoring that Marquez lacks. Elementary's column-level lineage feature does overlap with Marquez, though it derives lineage from dbt's DAG rather than from OpenLineage events.
Pricing Comparison
Scroll sideways to see all columns. With a keyboard, focus this table and use the arrow keys.
| Tool | Model | Starting Price | Self-Hosted Option |
|---|---|---|---|
| Marquez | Open Source | Free | Yes (only option) |
| DataHub | Freemium | Free (OSS) / Enterprise contact sales | Yes |
| OpenMetadata | Open Source | Free | Yes (also free SaaS sandbox) |
| Great Expectations | Open Source + Cloud | Free (GX Core) / GX Cloud tiers | Yes |
| Elementary | Freemium | Scale tier (contact sales) / Enterprise tier | Yes (dbt package) |
| Collibra | Enterprise | Contact sales | No (cloud-based) |
| Castor | Enterprise | Contact sales | No |
Marquez, DataHub, and OpenMetadata all offer fully free self-hosted deployments under Apache 2.0 licenses. Great Expectations provides its Python framework (GX Core) free and open-source, with GX Cloud available in Developer, Team, and Enterprise tiers. Elementary's open-source dbt package is free, but its cloud platform uses seat-based and table-count-based pricing across Scale, Enterprise, and Unlimited tiers. Collibra and Castor are enterprise-only with opaque pricing that typically starts in the tens of thousands annually.
When to Consider Switching
Switch from Marquez when your lineage needs expand into broader metadata management. If your team spends significant time manually connecting lineage data to catalog entries, quality checks, and governance policies, a unified platform like OpenMetadata or DataHub eliminates that integration burden. Marquez has 2,000+ GitHub stars compared to OpenMetadata's 11,200+ and Great Expectations' 11,400+, which reflects a focused community producing a compact set of integrations and measured feature development.
Consider switching if you need automated data quality monitoring. Marquez tells you where data flows but not whether it is correct. Teams that need anomaly detection, freshness monitoring, or validation rules will find themselves running Marquez alongside Great Expectations or Elementary anyway. At that point, a platform like OpenMetadata that bundles quality and lineage together reduces operational overhead.
If your organization is growing beyond a single data engineering team, Marquez's lack of role-based access control, ownership management, and collaboration features becomes a real limitation. DataHub and OpenMetadata offer fine-grained permissions, data ownership assignment, and team collaboration workflows that Marquez simply does not provide.
Stick with Marquez if you are deeply invested in the OpenLineage standard and need a lightweight, single-purpose lineage service. Its role as the OpenLineage reference implementation means it has first-class support for Airflow, Spark, Flink, dbt, and Dagster integrations without the complexity of a full metadata platform.
Migration Considerations
Migrating from Marquez to DataHub or OpenMetadata is straightforward because all three use similar metadata models and support OpenLineage events. DataHub can ingest OpenLineage events directly, so existing pipeline integrations that emit OpenLineage to Marquez can be redirected with minimal changes. OpenMetadata supports 120+ native connectors and can re-crawl your data sources to rebuild lineage independently of Marquez's stored data.
The learning curve varies significantly. Moving to DataHub or OpenMetadata means adopting a much larger system with more concepts to understand: data domains, glossaries, policies, and user management. Teams accustomed to Marquez's focused lineage API should expect a 2-4 week ramp-up period for the broader platforms. Moving to Great Expectations or Elementary is a different kind of migration entirely, as these tools complement rather than replace lineage and focus on validation and monitoring instead.
Data format compatibility is generally good across the open-source options. Marquez stores metadata in PostgreSQL, and its API responses follow the OpenLineage spec. Export your lineage graph through the Marquez REST API before migration, then use the target platform's ingestion framework to rebuild it. For teams running Airflow or Spark with OpenLineage integrations, the migration mostly involves changing the target endpoint URL in your OpenLineage configuration from Marquez to the new platform's compatible receiver.